Determining whether online users are authorized to access digital objects is central to preserving privacy. This paper presents the design, implementation, and deployment of Zanzibar, a global system for storing and evaluating access control lists. Zanzibar provides a uniform data model and configuration language for expressing a wide range of access control policies from hundreds of client services at Google, including Calendar, Cloud, Drive, Maps, Photos, and YouTube. Its authorization decisions respect causal ordering of user actions and thus provide external consistency amid changes to access control lists and object contents. Zanzibar scales to trillions of access control lists and millions of authorization requests per second to support services used by billions of people. It has maintained 95th-percentile latency of less than 10 milliseconds and availability of greater than 99.999% over 3 years of production use.
온라인 사용자가 디지털 객체에 접근할 권한이 있는지 판단하는 일은 프라이버시 보호의 핵심이다. 이 논문은 접근 제어 목록을 저장하고 평가하는 글로벌 시스템인 Zanzibar의 설계, 구현, 배포를 소개한다. Zanzibar는 Calendar, Cloud, Drive, Maps, Photos, YouTube를 포함한 Google의 수백 개 클라이언트 서비스가 요구하는 폭넓은 접근 제어 정책을 표현하기 위한 통일된 데이터 모델과 설정 언어를 제공한다. Zanzibar의 인가 결정은 사용자 행동의 인과적 순서를 준수하며, 따라서 접근 제어 목록과 객체 내용이 변경되는 와중에도 외부 일관성을 제공한다. Zanzibar는 수십억 명이 사용하는 서비스를 지원하기 위해 수조 개의 접근 제어 목록과 초당 수백만 건의 인가 요청으로 확장된다. Zanzibar는 3년이 넘는 프로덕션 사용 기간 동안 95번째 백분위수 지연 시간 10밀리초 미만, 가용성 99.999% 초과를 유지해 왔다.
Many online interactions require authorization checks to confirm that a user has permission to carry out an operation on a digital object. For example, web-based photo storage services typically allow photo owners to share some photos with friends while keeping other photos private. Such a service must check whether a photo has been shared with a user before allowing that user to view the photo. Robust authorization checks are central to preserving online privacy.
많은 온라인 상호작용에서는 사용자가 디지털 객체에 대해 어떤 작업을 수행할 권한이 있는지 확인하는 인가 검사가 필요하다. 예를 들어 웹 기반 사진 저장 서비스는 일반적으로 사진 소유자가 일부 사진은 친구와 공유하고 다른 사진은 비공개로 유지할 수 있게 한다. 이러한 서비스는 사용자가 사진을 보도록 허용하기 전에 그 사진이 해당 사용자와 공유되었는지 확인해야 한다. 견고한 인가 검사는 온라인 프라이버시 보호의 핵심이다.
This paper presents Zanzibar, a system for storing permissions and performing authorization checks based on the stored permissions. It is used by a wide array of services offered by Google, including Calendar, Cloud, Drive, Maps, Photos, and YouTube. Several of these services manage billions of objects on behalf of more than a billion users.
이 논문은 권한을 저장하고 저장된 권한을 기반으로 인가 검사를 수행하는 시스템인 Zanzibar를 소개한다. Zanzibar는 Calendar, Cloud, Drive, Maps, Photos, YouTube를 포함하여 Google이 제공하는 다양한 서비스에서 사용된다. 이들 서비스 중 몇몇은 10억 명이 넘는 사용자를 대신하여 수십억 개의 객체를 관리한다.
A unified authorization system offers important advantages over maintaining separate access control mechanisms for individual applications. First, it helps establish consistent semantics and user experience across applications. Second, it makes it easier for applications to interoperate, for example, to coordinate access control when an object from one application embeds an object from another application. Third, useful common infrastructure can be built on top of a unified access control system, in particular, a search index that respects access control and works across applications. Finally, as we show below, authorization poses unique challenges involving data consistency and scalability. It saves engineering resources to tackle them once across applications.
통합된 인가 시스템은 개별 애플리케이션마다 별도의 접근 제어 메커니즘을 유지하는 것에 비해 중요한 이점을 제공한다. 첫째, 애플리케이션 전반에 걸쳐 일관된 의미론과 사용자 경험을 확립하는 데 도움이 된다. 둘째, 애플리케이션 간 상호 운용을 쉽게 한다. 예를 들어 한 애플리케이션의 객체가 다른 애플리케이션의 객체를 포함(embed)할 때 접근 제어를 조율할 수 있다. 셋째, 통합된 접근 제어 시스템 위에 유용한 공통 인프라를 구축할 수 있으며, 특히 접근 제어를 준수하면서 여러 애플리케이션에 걸쳐 동작하는 검색 인덱스를 만들 수 있다. 마지막으로, 아래에서 보이듯이 인가는 데이터 일관성과 확장성에 관련된 고유한 과제를 안고 있다. 이를 애플리케이션 전반에 걸쳐 한 번에 해결하면 엔지니어링 자원이 절약된다.
- Correctness: It must ensure consistency of access control decisions to respect user intentions.
- Flexibility: It must support a rich set of access control policies as required by both consumer and enterprise applications.
- Low latency: It must respond quickly because authorization checks are often in the critical path of user interactions. Low latency at the tail is particularly important for serving search results, which often require tens to hundreds of checks.
- High availability: It must reliably respond to requests because, in the absence of explicit authorizations, client services would be forced to deny their users access.
- Large scale: It needs to protect billions of objects shared by billions of users. It must be deployed around the globe to be near its clients and their end users.
- 정확성: 사용자의 의도를 존중하도록 접근 제어 결정의 일관성을 보장해야 한다.
- 유연성: 소비자용 애플리케이션과 기업용 애플리케이션 모두가 요구하는 풍부한 접근 제어 정책을 지원해야 한다.
- 낮은 지연 시간: 인가 검사는 사용자 상호작용의 임계 경로(critical path)에 있는 경우가 많으므로 빠르게 응답해야 한다. 꼬리 구간의 낮은 지연 시간은 특히 검색 결과를 제공할 때 중요한데, 검색 결과에는 흔히 수십에서 수백 건의 검사가 필요하기 때문이다.
- 높은 가용성: 명시적인 인가가 없으면 클라이언트 서비스는 사용자의 접근을 거부할 수밖에 없으므로 요청에 안정적으로 응답해야 한다.
- 대규모: 수십억 명의 사용자가 공유하는 수십억 개의 객체를 보호해야 한다. 클라이언트와 그 최종 사용자 가까이에 있도록 전 세계에 배포되어야 한다.
Zanzibar achieves these goals through a combination of notable features. To provide flexibility, Zanzibar pairs a simple data model with a powerful configuration language. The language allows clients to define arbitrary relations between users and objects, such as owner, editor, commenter, and viewer. It includes set-algebraic operators such as intersection and union for specifying potentially complex access control policies in terms of those user-object relations. For example, an application can specify that users granted editing rights on a document are also allowed to comment on the document, but not all commenters are given editing rights.
Zanzibar는 주목할 만한 여러 기능을 조합하여 이러한 목표를 달성한다. 유연성을 제공하기 위해 Zanzibar는 단순한 데이터 모델에 강력한 설정 언어를 결합한다. 이 언어를 통해 클라이언트는 owner, editor, commenter, viewer와 같이 사용자와 객체 사이의 임의의 관계를 정의할 수 있다. 이 언어에는 교집합, 합집합과 같은 집합 대수 연산자가 포함되어 있어, 그러한 사용자-객체 관계를 바탕으로 잠재적으로 복잡한 접근 제어 정책을 지정할 수 있다. 예를 들어 애플리케이션은 문서에 대한 편집 권한을 부여받은 사용자는 그 문서에 댓글도 달 수 있지만, 모든 댓글 작성자에게 편집 권한이 주어지는 것은 아니라고 지정할 수 있다.
At runtime, Zanzibar allows clients to create, modify, and evaluate access control lists (ACLs) through a remote procedure call (RPC) interface. A simple ACL takes the form of “user U has relation R to object O”. More complex ACLs take the form of “set of users S has relation R to object O”, where S is itself specified in terms of another object-relation pair. ACLs can thus refer to other ACLs, for example to specify that the set of users who can comment on a video consists of the users who have been granted viewing rights on that specific video along with those with viewing permissions on the video channel.
런타임에 Zanzibar는 클라이언트가 원격 프로시저 호출(RPC) 인터페이스를 통해 접근 제어 목록(ACL)을 생성, 수정, 평가할 수 있게 한다. 단순한 ACL은 “사용자 U는 객체 O에 대해 관계 R을 가진다”의 형태를 띤다. 더 복잡한 ACL은 “사용자 집합 S는 객체 O에 대해 관계 R을 가진다”의 형태를 띠며, 여기서 S 자체는 다른 객체-관계 쌍으로 지정된다. 따라서 ACL은 다른 ACL을 참조할 수 있다. 예를 들어 어떤 동영상에 댓글을 달 수 있는 사용자 집합은 그 특정 동영상에 대한 시청 권한을 부여받은 사용자와 해당 동영상 채널에 대한 시청 권한을 가진 사용자로 구성된다고 지정할 수 있다.
Group memberships are an important class of ACL where the object is a group and the relation is semantically equivalent to member. Groups can contain other groups, which illustrates one of the challenges facing Zanzibar, namely that evaluating whether a user belongs to a group can entail following a long chain of nested group memberships.
그룹 멤버십은 객체가 그룹이고 관계가 의미상 member와 동등한 중요한 ACL 유형이다. 그룹은 다른 그룹을 포함할 수 있는데, 이는 Zanzibar가 직면한 과제 중 하나를 보여 준다. 즉, 사용자가 어떤 그룹에 속하는지 평가하려면 중첩된 그룹 멤버십의 긴 사슬을 따라가야 할 수 있다.
Authorization checks take the form of “does user U have relation R to object O?” and are evaluated by a collection of distributed servers. When a check request arrives to Zanzibar, the work to evaluate the check may fan out to multiple servers, for example when a group contains both individual members and other groups. Each of those servers may in turn contact other servers, for example to recursively traverse a hierarchy of group memberships.
인가 검사는 “사용자 U는 객체 O에 대해 관계 R을 가지는가?”의 형태를 띠며, 분산된 서버 집합에 의해 평가된다. 검사 요청이 Zanzibar에 도착하면, 검사를 평가하는 작업은 여러 서버로 팬아웃(fan out)될 수 있다. 예를 들어 그룹이 개별 멤버와 다른 그룹을 모두 포함하는 경우가 그렇다. 각 서버는 다시 다른 서버에 연락할 수 있는데, 예를 들어 그룹 멤버십의 계층 구조를 재귀적으로 순회하는 경우다.
Zanzibar operates at a global scale along multiple dimensions. It stores more than two trillion ACLs and performs millions of authorization checks per second. The ACL data does not lend itself to geographic partitioning because authorization checks for any object can come from anywhere in the world. Therefore, Zanzibar replicates all ACL data in tens of geographically distributed data centers and distributes load across thousands of servers around the world.
Zanzibar는 여러 차원에서 글로벌 규모로 운영된다. Zanzibar는 2조 개가 넘는 ACL을 저장하고 초당 수백만 건의 인가 검사를 수행한다. 어떤 객체에 대한 인가 검사든 전 세계 어디에서나 들어올 수 있으므로 ACL 데이터는 지리적 분할에 적합하지 않다. 따라서 Zanzibar는 모든 ACL 데이터를 지리적으로 분산된 수십 개의 데이터 센터에 복제하고, 전 세계 수천 대의 서버에 부하를 분산한다.
Zanzibar supports global consistency of access control decisions through two interrelated features. One, it respects the order in which ACL changes are committed to the underlying data store. Two, it can ensure that authorization checks are based on ACL data no older than a client-specified change. Thus, for example, a client can remove a user from a group and be assured that subsequent membership checks reflect that removal. Zanzibar provides these ordering properties by storing ACLs in a globally distributed database system with external consistency guarantees [15, 18].
Zanzibar는 서로 연관된 두 가지 기능을 통해 접근 제어 결정의 글로벌 일관성을 지원한다. 첫째, ACL 변경이 하부 데이터 저장소에 커밋되는 순서를 준수한다. 둘째, 인가 검사가 클라이언트가 지정한 변경보다 오래되지 않은 ACL 데이터를 기반으로 하도록 보장할 수 있다. 따라서 예를 들어 클라이언트는 그룹에서 사용자를 제거한 뒤 이후의 멤버십 검사가 그 제거를 반영한다고 확신할 수 있다. Zanzibar는 외부 일관성을 보장하는 글로벌 분산 데이터베이스 시스템에 ACL을 저장함으로써 이러한 순서 속성을 제공한다 [15, 18].
Zanzibar employs an array of techniques to achieve low latency and high availability in this globally distributed environment. Its consistency protocol allows the vast majority of requests to be served with locally replicated data, without requiring cross-region round trips. Zanzibar stores its data in normalized forms for consistency. It handles hot spots on normalized data by caching final and intermediate results, and by deduplicating simultaneous requests. It also applies techniques such as hedging requests and optimizing computations on deeply nested sets with limited denormalization. Zanzibar responds to more than 95% of authorization checks within 10 milliseconds and has maintained more than 99.999% availability for the last 3 years.
Zanzibar는 이러한 글로벌 분산 환경에서 낮은 지연 시간과 높은 가용성을 달성하기 위해 다양한 기법을 사용한다. Zanzibar의 일관성 프로토콜은 리전 간 왕복 없이 로컬에 복제된 데이터로 대부분의 요청을 처리할 수 있게 한다. Zanzibar는 일관성을 위해 데이터를 정규화된 형태로 저장한다. 정규화된 데이터의 핫스팟은 최종 결과와 중간 결과를 캐싱하고 동시 요청을 중복 제거하여 처리한다. 또한 요청 헤징, 제한적인 비정규화를 통한 깊게 중첩된 집합에 대한 연산 최적화 같은 기법도 적용한다. Zanzibar는 인가 검사의 95% 이상에 10밀리초 이내로 응답하며, 지난 3년간 99.999%가 넘는 가용성을 유지해 왔다.
The main contributions of this paper lie in conveying the engineering challenges in building and deploying a consistent, world-scale authorization system. While most elements of Zanzibar’s design have their roots in previous research, this paper provides a record of the features and techniques Zanzibar brings together to satisfy its stringent requirements for correctness, flexibility, latency, availability, and scalability. The paper also highlights lessons learned from operating Zanzibar in service of a diverse set of demanding clients.
이 논문의 주요 기여는 일관되고 세계적 규모를 가진 인가 시스템을 구축하고 배포하는 데 따르는 엔지니어링 과제를 전달하는 데 있다. Zanzibar 설계의 요소 대부분은 기존 연구에 뿌리를 두고 있지만, 이 논문은 정확성, 유연성, 지연 시간, 가용성, 확장성에 대한 엄격한 요구 사항을 충족하기 위해 Zanzibar가 결합한 기능과 기법을 기록으로 남긴다. 또한 까다롭고 다양한 클라이언트를 위해 Zanzibar를 운영하면서 얻은 교훈을 조명한다.
This section describes Zanzibar’s data model, configuration language, and application programming interface (API).
이 절에서는 Zanzibar의 데이터 모델, 설정 언어, 애플리케이션 프로그래밍 인터페이스(API)를 설명한다.
In Zanzibar, ACLs are collections of object-user or object-object relations represented as relation tuples. Groups are simply ACLs with membership semantics. Relation tuples have efficient binary encodings, but in this paper we represent them using a convenient text notation:
Zanzibar에서 ACL은 관계 튜플로 표현되는 객체-사용자 또는 객체-객체 관계의 모음이다. 그룹은 단순히 멤버십 의미론을 갖는 ACL이다. 관계 튜플에는 효율적인 바이너리 인코딩이 있지만, 이 논문에서는 편리한 텍스트 표기법을 사용하여 나타낸다.
where ⟨namespace⟩ and ⟨relation⟩ are predefined in client configurations (§2.3), ⟨object_id⟩ is a string, and ⟨user_id⟩ is an integer. The primary keys required to identify a relation tuple are ⟨namespace⟩, ⟨object_id⟩, ⟨relation⟩, and ⟨user⟩. One feature worth noting is that a ⟨userset⟩ allows ACLs to refer to groups and thus supports representing nested group membership.
여기서 ⟨namespace⟩와 ⟨relation⟩은 클라이언트 설정에 미리 정의되어 있고(§2.3), ⟨object_id⟩는 문자열이며, ⟨user_id⟩는 정수다. 관계 튜플을 식별하는 데 필요한 기본 키는 ⟨namespace⟩, ⟨object_id⟩, ⟨relation⟩, ⟨user⟩다. 주목할 만한 특징 하나는 ⟨userset⟩을 통해 ACL이 그룹을 참조할 수 있으며, 따라서 중첩된 그룹 멤버십을 표현할 수 있다는 점이다.
Table 1 shows some example tuples and corresponding semantics. While some relations (e.g. viewer) define access control directly, others (e.g. parent, pointing to a folder) only define abstract relations between objects. These abstract relations may indirectly affect access control given userset rewrite rules specified in namespace configs (§2.3.1).
표 1은 몇 가지 예시 튜플과 그에 대응하는 의미를 보여 준다. 일부 관계(예: viewer)는 접근 제어를 직접 정의하는 반면, 다른 관계(예: 폴더를 가리키는 parent)는 객체 사이의 추상적인 관계만 정의한다. 이러한 추상적 관계는 네임스페이스 설정에 지정된 유저셋 재작성 규칙(§2.3.1)에 따라 간접적으로 접근 제어에 영향을 줄 수 있다.
Table 1: Example relation tuples. “#...” represents a relation that does not affect the semantics of the tuple.
표 1: 관계 튜플의 예. “#...”는 튜플의 의미에 영향을 주지 않는 관계를 나타낸다.
Defining our data model around tuples, instead of per-object ACLs, allows us to unify the concepts of ACLs and groups and to support efficient reads and incremental updates, as we will see in §2.4.
객체별 ACL 대신 튜플을 중심으로 데이터 모델을 정의하면 ACL과 그룹이라는 개념을 통합할 수 있고, §2.4에서 보겠지만 효율적인 읽기와 점진적 갱신을 지원할 수 있다.
ACL checks must respect the order in which users modify ACLs and object contents to avoid unexpected sharing behaviors. Specifically, our clients care about preventing the “new enemy” problem, which can arise when we fail to respect the ordering between ACL updates or when we apply old ACLs to new content. Consider these two examples:
ACL 검사는 예상치 못한 공유 동작을 피하기 위해 사용자가 ACL과 객체 내용을 수정하는 순서를 준수해야 한다. 특히 클라이언트는 “new enemy” 문제를 방지하는 데 관심이 있는데, 이 문제는 ACL 갱신 사이의 순서를 준수하지 못하거나 새 콘텐츠에 오래된 ACL을 적용할 때 발생할 수 있다. 다음 두 예를 생각해 보자.
Example A: Neglecting ACL update order
- Alice removes Bob from the ACL of a folder;
- Alice then asks Charlie to move new documents to the folder, where document ACLs inherit from folder ACLs;
- Bob should not be able to see the new documents, but may do so if the ACL check neglects the ordering between the two ACL changes.
예 A: ACL 갱신 순서 무시
- Alice가 폴더의 ACL에서 Bob을 제거한다.
- 이어서 Alice가 Charlie에게 새 문서들을 그 폴더로 옮겨 달라고 요청한다. 이때 문서의 ACL은 폴더의 ACL을 상속한다.
- Bob은 새 문서들을 볼 수 없어야 하지만, ACL 검사가 두 ACL 변경 사이의 순서를 무시하면 볼 수 있게 될 수도 있다.
Example B: Misapplying old ACL to new content
- Alice removes Bob from the ACL of a document;
- Alice then asks Charlie to add new contents to the document;
- Bob should not be able to see the new contents, but may do so if the ACL check is evaluated with a stale ACL from before Bob’s removal.
예 B: 새 콘텐츠에 오래된 ACL을 잘못 적용
- Alice가 문서의 ACL에서 Bob을 제거한다.
- 이어서 Alice가 Charlie에게 그 문서에 새 내용을 추가해 달라고 요청한다.
- Bob은 새 내용을 볼 수 없어야 하지만, ACL 검사가 Bob이 제거되기 전의 오래된 ACL로 평가되면 볼 수 있게 될 수도 있다.
Preventing the “new enemy” problem requires Zanzibar to understand and respect the causal ordering between ACL or content updates, including updates on different ACLs or objects and those coordinated via channels invisible to Zanzibar. Hence Zanzibar must provide two key consistency properties: external consistency [18] and snapshot reads with bounded staleness.
“new enemy” 문제를 방지하려면 Zanzibar는 ACL 또는 콘텐츠 갱신 사이의 인과적 순서를 이해하고 준수해야 하며, 여기에는 서로 다른 ACL이나 객체에 대한 갱신, 그리고 Zanzibar가 볼 수 없는 채널을 통해 조율된 갱신도 포함된다. 따라서 Zanzibar는 두 가지 핵심 일관성 속성, 즉 외부 일관성 [18]과 오래된 정도(staleness)가 제한된 스냅샷 읽기를 제공해야 한다.
External consistency allows Zanzibar to assign a timestamp to each ACL or content update, such that two causally related updates will be assigned timestamps that reflect the causal order: . With causally meaningful timestamps, a snapshot read of the ACL database at timestamp , which observes all updates with timestamps , will respect ordering between ACL updates. That is, if the read observes an update , it will observe all updates that happen causally before .
외부 일관성을 통해 Zanzibar는 각 ACL 또는 콘텐츠 갱신에 타임스탬프를 할당할 수 있으며, 인과적으로 관련된 두 갱신 에는 인과적 순서를 반영하는 타임스탬프 가 할당된다. 인과적으로 의미 있는 타임스탬프가 있으면, 타임스탬프 에서 ACL 데이터베이스를 읽는 스냅샷 읽기는 타임스탬프가 인 모든 갱신을 관측하므로 ACL 갱신 사이의 순서를 준수하게 된다. 즉, 읽기가 갱신 를 관측한다면 보다 인과적으로 앞서 일어난 모든 갱신도 관측하게 된다.
Furthermore, to avoid applying old ACLs to new contents, the ACL check evaluation snapshot must not be staler than the causal timestamp assigned to the content update. Given a content update at timestamp , a snapshot read at timestamp ensures that all ACL updates that happen causally before the content update will be observed by the ACL check.
나아가 새 콘텐츠에 오래된 ACL을 적용하지 않으려면, ACL 검사 평가 스냅샷이 콘텐츠 갱신에 할당된 인과적 타임스탬프보다 오래되어서는 안 된다. 타임스탬프 에서 이루어진 콘텐츠 갱신이 주어졌을 때, 타임스탬프 에서의 스냅샷 읽기는 콘텐츠 갱신보다 인과적으로 앞서 일어난 모든 ACL 갱신을 ACL 검사가 관측하도록 보장한다.
To provide external consistency and snapshot reads with bounded staleness, we store ACLs in the Spanner global database system [15]. Spanner’s TrueTime mechanism assigns each ACL write a microsecond-resolution timestamp, such that the timestamps of writes reflect the causal ordering between writes, and thereby provide external consistency. We evaluate each ACL check at a single snapshot timestamp across multiple database reads, so that all writes with timestamps up to the check snapshot, and only those writes, are visible to the ACL check.
외부 일관성과 오래된 정도가 제한된 스냅샷 읽기를 제공하기 위해, 우리는 ACL을 Spanner 글로벌 데이터베이스 시스템 [15]에 저장한다. Spanner의 TrueTime 메커니즘은 각 ACL 쓰기에 마이크로초 해상도의 타임스탬프를 할당하며, 쓰기의 타임스탬프가 쓰기 사이의 인과적 순서를 반영하도록 하여 외부 일관성을 제공한다. 우리는 각 ACL 검사를 여러 데이터베이스 읽기에 걸쳐 단일 스냅샷 타임스탬프에서 평가하므로, 검사 스냅샷까지의 타임스탬프를 가진 모든 쓰기, 그리고 오직 그 쓰기만이 ACL 검사에 보인다.
To avoid evaluating checks for new contents using stale ACLs, one could try to always evaluate at the latest snapshot such that the check result reflects all ACL writes up to the check call. However, such evaluation would require global data synchronization with high-latency round trips and limited availability. Instead, we design the following protocol to allow most checks to be evaluated on already replicated data with cooperation from Zanzibar clients:
새 콘텐츠에 대한 검사를 오래된 ACL로 평가하지 않기 위해, 검사 결과가 검사 호출 시점까지의 모든 ACL 쓰기를 반영하도록 항상 최신 스냅샷에서 평가하는 방법을 시도해 볼 수 있다. 그러나 그러한 평가에는 지연 시간이 큰 왕복을 수반하는 글로벌 데이터 동기화가 필요하고 가용성도 제한된다. 대신 우리는 Zanzibar 클라이언트의 협조를 받아 대부분의 검사를 이미 복제된 데이터로 평가할 수 있도록 다음 프로토콜을 설계한다.
- A Zanzibar client requests an opaque consistency token called a zookie for each content version, via a content-change ACL check (§2.4.4) when the content modification is about to be saved. Zanzibar encodes a current global timestamp in the zookie and ensures that all prior ACL writes have lower timestamps. The client stores the zookie with the content change in an atomic write to the client storage. Note that the content-change check does not need to be evaluated in the same transaction as the application content modification, but only has to be triggered when the user modifies the contents.
- The client sends this zookie in subsequent ACL check requests to ensure that the check snapshot is at least as fresh as the timestamp for the content version.
- Zanzibar 클라이언트는 콘텐츠 수정 사항이 저장되려 할 때 content-change ACL 검사(§2.4.4)를 통해 각 콘텐츠 버전에 대해 zookie라는 불투명한 일관성 토큰을 요청한다. Zanzibar는 현재의 글로벌 타임스탬프를 zookie에 인코딩하고, 이전의 모든 ACL 쓰기가 더 낮은 타임스탬프를 갖도록 보장한다. 클라이언트는 zookie를 콘텐츠 변경과 함께 클라이언트 저장소에 원자적 쓰기로 저장한다. content-change 검사는 애플리케이션 콘텐츠 수정과 같은 트랜잭션에서 평가될 필요는 없으며, 사용자가 내용을 수정할 때 트리거되기만 하면 된다는 점에 유의하라.
- 클라이언트는 이후의 ACL 검사 요청에 이 zookie를 보내, 검사 스냅샷이 적어도 해당 콘텐츠 버전의 타임스탬프만큼 최신이도록 보장한다.
External consistency and snapshot reads with staleness bounded by zookie prevent the “new enemy” problem. In Example A, ACL updates A1 and A2 will be assigned timestamps , respectively. Bob will not be able to see the new documents added by Charlie: if a check is evaluated at , the document ACLs will not include the folder ACL; if a check is evaluated at , the check will observe update A1, which removed Bob from the folder ACL. In Example B, Bob will not see the new contents added to the document. For Bob to see the new contents, the check must be evaluated with a zookie , the timestamp assigned to the content update. Because , such a check will also observe the ACL update B1, which removed Bob from the ACL.
외부 일관성과 zookie로 오래된 정도가 제한되는 스냅샷 읽기는 “new enemy” 문제를 방지한다. 예 A에서 ACL 갱신 A1과 A2에는 각각 타임스탬프 가 할당된다. Bob은 Charlie가 추가한 새 문서들을 볼 수 없다. 검사가 에서 평가되면 문서 ACL에 폴더 ACL이 포함되지 않고, 검사가 에서 평가되면 검사는 폴더 ACL에서 Bob을 제거한 갱신 A1을 관측하기 때문이다. 예 B에서 Bob은 문서에 추가된 새 내용을 볼 수 없다. Bob이 새 내용을 보려면 검사가 인 zookie, 즉 콘텐츠 갱신에 할당된 타임스탬프 이상의 zookie로 평가되어야 한다. 이므로 그러한 검사는 ACL에서 Bob을 제거한 ACL 갱신 B1도 관측하게 된다.
The zookie protocol is a key feature of Zanzibar’s consistency model. It ensures that Zanzibar respects causal ordering between ACL and content updates, but otherwise grants Zanzibar freedom to choose evaluation timestamps so as to meet its latency and availability goals. The freedom arises from the protocol’s at-least-as-fresh semantics, which allow Zanzibar to choose any timestamp fresher than the one encoded in a zookie. Such freedom in turn allows Zanzibar to serve most checks at a default staleness with already replicated data (§3.2.1) and to quantize evaluation timestamps to avoid hot spots (§3.2.5).
zookie 프로토콜은 Zanzibar 일관성 모델의 핵심 기능이다. 이 프로토콜은 Zanzibar가 ACL 갱신과 콘텐츠 갱신 사이의 인과적 순서를 준수하도록 보장하면서도, 그 밖의 경우에는 지연 시간과 가용성 목표를 충족하도록 평가 타임스탬프를 선택할 자유를 Zanzibar에 부여한다. 이 자유는 프로토콜의 “최소한 그만큼은 최신(at-least-as-fresh)” 의미론에서 비롯되며, 이 의미론 덕분에 Zanzibar는 zookie에 인코딩된 타임스탬프보다 최신인 어떤 타임스탬프든 선택할 수 있다. 이러한 자유 덕분에 Zanzibar는 대부분의 검사를 이미 복제된 데이터로 기본 오래된 정도에서 처리할 수 있고(§3.2.1), 핫스팟을 피하기 위해 평가 타임스탬프를 양자화할 수 있다(§3.2.5).
Before clients can store relation tuples in Zanzibar, they must configure their namespaces. A namespace configuration specifies its relations as well as its storage parameters. Each relation has a name, which is a client-defined string such as viewer or editor, and a relation config. Storage parameters include sharding settings and an encoding for object IDs that helps Zanzibar optimize storage of integer, string, and other object ID formats.
클라이언트는 Zanzibar에 관계 튜플을 저장하기 전에 네임스페이스를 설정해야 한다. 네임스페이스 설정은 그 네임스페이스의 관계와 저장소 매개변수를 지정한다. 각 관계에는 viewer나 editor처럼 클라이언트가 정의한 문자열인 이름과 관계 설정이 있다. 저장소 매개변수에는 샤딩 설정, 그리고 Zanzibar가 정수, 문자열 및 기타 객체 ID 형식의 저장을 최적화하는 데 도움이 되는 객체 ID 인코딩이 포함된다.
While relation tuples reflect relationships between objects and users, they do not completely define the effective ACLs. For example, some clients specify that users with editor permissions on each object should have viewer permission on the same object. While such relationships between relations can be represented by a relation tuple per object, storing a tuple for each object in a namespace would be wasteful and make it hard to make modifications across all objects. Instead, we let clients define object-agnostic relationships via userset rewrite rules in relation configs. Figure 1 demonstrates a simple namespace configuration with concentric relations, where viewer contains editor, and editor contains owner.
관계 튜플은 객체와 사용자 사이의 관계를 반영하지만, 실효 ACL을 완전히 정의하지는 않는다. 예를 들어 어떤 클라이언트는 각 객체에 대해 editor 권한을 가진 사용자가 같은 객체에 대해 viewer 권한도 가져야 한다고 지정한다. 이러한 관계 간의 관계는 객체마다 관계 튜플 하나로 표현할 수 있지만, 네임스페이스의 모든 객체에 대해 튜플을 저장하는 것은 낭비이며 모든 객체에 걸친 수정을 어렵게 만든다. 대신 우리는 클라이언트가 관계 설정의 유저셋 재작성 규칙을 통해 객체와 무관한 관계를 정의할 수 있게 한다. 그림 1은 viewer가 editor를 포함하고 editor가 owner를 포함하는 동심원 관계를 가진 간단한 네임스페이스 설정을 보여 준다.
Figure 1: Simple namespace configuration with concentric relations on documents. All owners are editors, and all editors are viewers. Further, viewers of the parent folder are also viewers of the document.
그림 1: 문서에 대한 동심원 관계를 가진 간단한 네임스페이스 설정. 모든 소유자는 편집자이고, 모든 편집자는 열람자다. 또한 상위 폴더의 열람자는 그 문서의 열람자이기도 하다.
Userset rewrite rules are defined per relation in a namespace. Each rule specifies a function that takes an object ID as input and outputs a userset expression tree. Each leaf node of the tree can be any of the following:
유저셋 재작성 규칙은 네임스페이스 내에서 관계별로 정의된다. 각 규칙은 객체 ID를 입력으로 받아 유저셋 표현식 트리를 출력하는 함수를 지정한다. 트리의 각 리프 노드는 다음 중 하나일 수 있다.
_this: Returns all users from stored relation tuples for the ⟨object#relation⟩ pair, including indirect ACLs referenced by usersets from the tuples. This is the default behavior when no rewrite rule is specified.computed_userset: Computes, for the input object, a new userset. For example, this allows the userset expression for aviewerrelation to refer to theeditoruserset on the same object, thus offering an ACL inheritance capability between relations.tuple_to_userset: Computes a tupleset (§2.4.1) from the input object, fetches relation tuples matching the tupleset, and computes a userset from every fetched relation tuple. This flexible primitive allows our clients to express complex policies such as “look up the parent folder of the document and inherit its viewers”.
_this: ⟨object#relation⟩ 쌍에 대해 저장된 관계 튜플의 모든 사용자를 반환하며, 튜플의 유저셋이 참조하는 간접 ACL도 포함한다. 재작성 규칙이 지정되지 않았을 때의 기본 동작이다.computed_userset: 입력 객체에 대해 새로운 유저셋을 계산한다. 예를 들어 이를 통해viewer관계의 유저셋 표현식이 같은 객체의editor유저셋을 참조할 수 있으므로, 관계 사이의 ACL 상속 기능을 제공한다.tuple_to_userset: 입력 객체로부터 튜플셋(§2.4.1)을 계산하고, 그 튜플셋과 일치하는 관계 튜플을 가져온 다음, 가져온 각 관계 튜플로부터 유저셋을 계산한다. 이 유연한 기본 요소를 통해 클라이언트는 “문서의 상위 폴더를 찾아 그 열람자를 상속한다”와 같은 복잡한 정책을 표현할 수 있다.
A userset expression can also be composed of multiple sub-expressions, combined by operations such as union, intersection, and exclusion.
유저셋 표현식은 여러 하위 표현식을 합집합, 교집합, 차집합(exclusion) 같은 연산으로 결합하여 구성할 수도 있다.
In addition to supporting ACL checks, Zanzibar also provides APIs for clients to read and write relation tuples, watch tuple updates, and inspect the effective ACLs.
ACL 검사를 지원하는 것 외에도 Zanzibar는 클라이언트가 관계 튜플을 읽고 쓰고, 튜플 갱신을 감시하고, 실효 ACL을 검사할 수 있는 API를 제공한다.
A concept used throughout these API methods is that of a zookie. A zookie is an opaque byte sequence encoding a globally meaningful timestamp that reflects an ACL write, a client content version, or a read snapshot. Zookies in ACL read and check requests specify staleness bounds for snapshot reads, thus providing one of Zanzibar’s core consistency properties. We choose to use an opaque cookie instead of the actual timestamp to discourage our clients from choosing arbitrary timestamps and to allow future extensions.
이 API 메서드 전반에 걸쳐 사용되는 개념이 zookie다. zookie는 ACL 쓰기, 클라이언트 콘텐츠 버전 또는 읽기 스냅샷을 반영하는, 전역적으로 의미 있는 타임스탬프를 인코딩한 불투명한 바이트 시퀀스다. ACL 읽기 및 검사 요청의 zookie는 스냅샷 읽기의 오래된 정도 한도를 지정하며, 이를 통해 Zanzibar의 핵심 일관성 속성 중 하나를 제공한다. 우리는 클라이언트가 임의의 타임스탬프를 선택하지 않도록 유도하고 향후 확장을 허용하기 위해, 실제 타임스탬프 대신 불투명한 쿠키를 사용하기로 했다.
Our clients read relation tuples to display ACLs or group membership to users, or to prepare for a subsequent write. A read request specifies one or multiple tuplesets and an optional zookie.
클라이언트는 사용자에게 ACL이나 그룹 멤버십을 표시하거나 후속 쓰기를 준비하기 위해 관계 튜플을 읽는다. 읽기 요청은 하나 이상의 튜플셋과 선택적인 zookie를 지정한다.
Each tupleset specifies keys of a set of relation tuples. The set can include a single tuple key, or all tuples with a given object ID or userset in a namespace, optionally constrained by a relation name. With the tuplesets, clients can look up a specific membership entry, read all entries in an ACL or group, or look up all groups with a given user as a direct member. All tuplesets in a read request are processed at a single snapshot.
각 튜플셋은 관계 튜플 집합의 키를 지정한다. 이 집합은 단일 튜플 키를 포함할 수도 있고, 네임스페이스에서 주어진 객체 ID나 유저셋을 가진 모든 튜플을 포함할 수도 있으며, 선택적으로 관계 이름으로 제한할 수 있다. 튜플셋을 사용하여 클라이언트는 특정 멤버십 항목을 조회하거나, ACL 또는 그룹의 모든 항목을 읽거나, 주어진 사용자를 직접 멤버로 갖는 모든 그룹을 조회할 수 있다. 읽기 요청의 모든 튜플셋은 단일 스냅샷에서 처리된다.
With the zookie, clients can request a read snapshot no earlier than a previous write if the zookie from the write response is given in the read request, or at the same snapshot as a previous read if the zookie from the earlier read response is given in the subsequent request. If the request doesn’t contain a zookie, Zanzibar will choose a reasonably recent snapshot, possibly offering a lower-latency response than if a zookie were provided.
zookie를 사용하여 클라이언트는 쓰기 응답의 zookie를 읽기 요청에 넣으면 이전 쓰기보다 이르지 않은 읽기 스냅샷을 요청할 수 있고, 이전 읽기 응답의 zookie를 후속 요청에 넣으면 이전 읽기와 같은 스냅샷을 요청할 수 있다. 요청에 zookie가 포함되어 있지 않으면 Zanzibar는 적당히 최근의 스냅샷을 선택하며, zookie가 제공된 경우보다 더 낮은 지연 시간으로 응답할 수 있다.
Read results only depend on contents of relation tuples and do not reflect userset rewrite rules. For example, even if the viewer userset always includes the owner userset, reading tuples with the viewer relation will not return tuples with the owner relation. Clients that need to understand the effective userset can use the Expand API (§2.4.5).
읽기 결과는 관계 튜플의 내용에만 의존하며 유저셋 재작성 규칙을 반영하지 않는다. 예를 들어 viewer 유저셋이 항상 owner 유저셋을 포함하더라도, viewer 관계를 가진 튜플을 읽으면 owner 관계를 가진 튜플은 반환되지 않는다. 실효 유저셋을 파악해야 하는 클라이언트는 Expand API(§2.4.5)를 사용할 수 있다.
Clients may modify a single relation tuple to add or remove an ACL. They may also modify all tuples related to an object via a read-modify-write process with optimistic concurrency control [21] that uses a read RPC followed by a write RPC:
클라이언트는 ACL을 추가하거나 제거하기 위해 단일 관계 튜플을 수정할 수 있다. 또한 낙관적 동시성 제어 [21]를 사용하는 읽기-수정-쓰기 과정을 통해 객체와 관련된 모든 튜플을 수정할 수도 있는데, 이 과정은 read RPC 다음에 write RPC를 사용한다.
- Read all relation tuples of an object, including a per-object “lock” tuple.
- Generate the tuples to write or delete. Send the writes, along with a touch on the lock tuple, to Zanzibar, with the condition that the writes will be committed only if the lock tuple has not been modified since the read.
- If the write condition is not met, go back to step 1.
- 객체별 “락” 튜플을 포함하여 객체의 모든 관계 튜플을 읽는다.
- 쓰거나 삭제할 튜플을 생성한다. 락 튜플에 대한 터치(touch)와 함께 쓰기를 Zanzibar에 보내되, 읽기 이후 락 튜플이 수정되지 않은 경우에만 쓰기가 커밋된다는 조건을 붙인다.
- 쓰기 조건이 충족되지 않으면 1단계로 돌아간다.
The lock tuple is just a regular relation tuple used by clients to detect write races.
락 튜플은 클라이언트가 쓰기 경합을 감지하기 위해 사용하는 일반 관계 튜플일 뿐이다.
Some clients maintain secondary indices of relation tuples in Zanzibar. They can do so with our Watch API. A watch request specifies one or more namespaces and a zookie representing the time to start watching. A watch response contains all tuple modification events in ascending timestamp order, from the requested start timestamp to a timestamp encoded in a heartbeat zookie included in the watch response. The client can use the heartbeat zookie to resume watching where the previous watch response left off.
일부 클라이언트는 Zanzibar에 있는 관계 튜플의 보조 인덱스를 유지한다. 클라이언트는 Watch API로 이를 수행할 수 있다. Watch 요청은 하나 이상의 네임스페이스와 감시를 시작할 시점을 나타내는 zookie를 지정한다. Watch 응답에는 요청된 시작 타임스탬프부터 Watch 응답에 포함된 하트비트 zookie에 인코딩된 타임스탬프까지의 모든 튜플 수정 이벤트가 타임스탬프 오름차순으로 담긴다. 클라이언트는 하트비트 zookie를 사용하여 이전 Watch 응답이 끝난 지점부터 감시를 재개할 수 있다.
A check request specifies a userset, represented by ⟨object#relation⟩, a putative user, often represented by an authentication token, and a zookie corresponding to the desired object version. Like reads, a check is always evaluated at a consistent snapshot no earlier than the given zookie.
Check 요청은 ⟨object#relation⟩으로 표현되는 유저셋, 흔히 인증 토큰으로 표현되는 대상 사용자(putative user), 그리고 원하는 객체 버전에 대응하는 zookie를 지정한다. 읽기와 마찬가지로 Check는 항상 주어진 zookie보다 이르지 않은 일관된 스냅샷에서 평가된다.
To authorize application content modifications, our clients send a special type of check request, a content-change check. A content-change check request does not carry a zookie and is evaluated at the latest snapshot. If a content change is authorized, the check response includes a zookie for clients to store along with object contents and use for subsequent checks of the content version. The zookie encodes the evaluation snapshot and captures any possible causality from ACL changes to content changes, because the zookie’s timestamp will be greater than that of the ACL updates that protect the new content (§2.2).
애플리케이션 콘텐츠 수정을 인가하기 위해 클라이언트는 특별한 유형의 Check 요청인 content-change 검사를 보낸다. content-change 검사 요청은 zookie를 포함하지 않으며 최신 스냅샷에서 평가된다. 콘텐츠 변경이 인가되면 검사 응답에는 zookie가 포함되며, 클라이언트는 이를 객체 내용과 함께 저장했다가 해당 콘텐츠 버전에 대한 후속 검사에 사용한다. zookie는 평가 스냅샷을 인코딩하며, ACL 변경에서 콘텐츠 변경으로 이어지는 모든 가능한 인과 관계를 포착한다. zookie의 타임스탬프는 새 콘텐츠를 보호하는 ACL 갱신의 타임스탬프보다 크기 때문이다(§2.2).
The Expand API returns the effective userset given an ⟨object#relation⟩ pair and an optional zookie. Unlike the Read API, Expand follows indirect references expressed through userset rewrite rules. The result is represented by a userset tree whose leaf nodes are user IDs or usersets pointing to other ⟨object#relation⟩ pairs, and intermediate nodes represent union, intersection, or exclusion operators. Expand is crucial for our clients to reason about the complete set of users and groups that have access to their objects, which allows them to build efficient search indices for access-controlled content.
Expand API는 ⟨object#relation⟩ 쌍과 선택적인 zookie가 주어지면 실효 유저셋을 반환한다. Read API와 달리 Expand는 유저셋 재작성 규칙을 통해 표현된 간접 참조를 따라간다. 결과는 유저셋 트리로 표현되는데, 리프 노드는 사용자 ID 또는 다른 ⟨object#relation⟩ 쌍을 가리키는 유저셋이고, 중간 노드는 합집합, 교집합, 차집합 연산자를 나타낸다. Expand는 클라이언트가 자신의 객체에 접근할 수 있는 사용자와 그룹의 전체 집합을 파악하는 데 매우 중요하며, 이를 통해 접근 제어되는 콘텐츠에 대한 효율적인 검색 인덱스를 구축할 수 있다.
Figure 2 shows the architecture of the Zanzibar system. aclservers are the main server type. They are organized in clusters and respond to Check, Read, Expand, and Write requests. Requests arrive at any server in a cluster and that server fans out the work to other servers in the cluster as necessary. Those servers may in turn contact other servers to compute intermediate results. The initial server gathers the final result and returns it to the client.
그림 2는 Zanzibar 시스템의 아키텍처를 보여 준다. aclservers는 주된 서버 유형이다. 이 서버들은 클러스터로 구성되며 Check, Read, Expand, Write 요청에 응답한다. 요청은 클러스터 내 임의의 서버에 도착하고, 그 서버는 필요에 따라 클러스터 내 다른 서버로 작업을 팬아웃한다. 그 서버들은 다시 중간 결과를 계산하기 위해 다른 서버에 연락할 수 있다. 처음 요청을 받은 서버가 최종 결과를 모아 클라이언트에 반환한다.
Zanzibar stores ACLs and their metadata in Spanner databases. There is one database to store relation tuples for each client namespace, one database to hold all namespace configurations, and one changelog database shared across all namespaces. aclservers read and write those databases in the course of responding to client requests.
Zanzibar는 ACL과 그 메타데이터를 Spanner 데이터베이스에 저장한다. 클라이언트 네임스페이스마다 관계 튜플을 저장하는 데이터베이스가 하나씩 있고, 모든 네임스페이스 설정을 보관하는 데이터베이스가 하나, 그리고 모든 네임스페이스가 공유하는 변경 로그 데이터베이스가 하나 있다. aclservers는 클라이언트 요청에 응답하는 과정에서 이 데이터베이스들을 읽고 쓴다.
watchservers are a specialized server type that respond to Watch requests. They tail the changelog and serve a stream of namespace changes to clients in near real time.
watchservers는 Watch 요청에 응답하는 특수한 서버 유형이다. 이 서버들은 변경 로그를 추적(tail)하여 네임스페이스 변경 스트림을 거의 실시간으로 클라이언트에 제공한다.
Zanzibar periodically runs a data processing pipeline to perform a variety of offline functions across all Zanzibar data in Spanner. One such function is to produce dumps of the relation tuples in each namespace at a known snapshot timestamp. Another is to garbage-collect tuple versions older than a threshold configured per namespace.
Zanzibar는 주기적으로 데이터 처리 파이프라인을 실행하여 Spanner에 있는 모든 Zanzibar 데이터에 대해 다양한 오프라인 기능을 수행한다. 그러한 기능 중 하나는 알려진 스냅샷 타임스탬프에서 각 네임스페이스의 관계 튜플 덤프를 생성하는 것이다. 또 다른 기능은 네임스페이스별로 설정된 임계값보다 오래된 튜플 버전을 가비지 컬렉션하는 것이다.
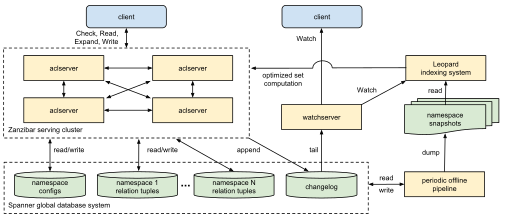
Figure 2: Zanzibar architecture. Arrows indicate the direction of data flow.
그림 2: Zanzibar 아키텍처. 화살표는 데이터 흐름의 방향을 나타낸다.
Leopard is an indexing system used to optimize operations on large and deeply nested sets. It reads periodic snapshots of ACL data and watches for changes between snapshots. It performs transformations on that data, such as denormalization, and responds to requests from aclservers.
Leopard는 크고 깊게 중첩된 집합에 대한 연산을 최적화하는 데 사용되는 인덱싱 시스템이다. Leopard는 ACL 데이터의 주기적 스냅샷을 읽고 스냅샷 사이의 변경을 감시한다. 그 데이터에 대해 비정규화 같은 변환을 수행하고 aclservers의 요청에 응답한다.
The rest of this section presents the implementation of these architectural elements in more detail.
이 절의 나머지 부분에서는 이러한 아키텍처 요소의 구현을 더 자세히 설명한다.
We store relation tuples of each namespace in a separate database, where each row is identified by primary key (shard ID, object ID, relation, user, commit timestamp). Multiple tuple versions are stored on different rows, so that we can evaluate checks and reads at any timestamp within the garbage collection window. The ordering of primary keys allows us to look up all relation tuples for a given object ID or (object ID, relation) pair.
우리는 각 네임스페이스의 관계 튜플을 별도의 데이터베이스에 저장하며, 각 행은 기본 키 (샤드 ID, 객체 ID, 관계, 사용자, 커밋 타임스탬프)로 식별된다. 여러 튜플 버전이 서로 다른 행에 저장되므로, 가비지 컬렉션 기간 내의 어떤 타임스탬프에서든 검사와 읽기를 평가할 수 있다. 기본 키의 순서 덕분에 주어진 객체 ID 또는 (객체 ID, 관계) 쌍에 대한 모든 관계 튜플을 조회할 수 있다.
Our clients configure sharding of a namespace according to its data pattern. Usually the shard ID is determined solely by the object ID. In some cases, for example, when a namespace stores groups with very large numbers of members, the shard ID is computed from both object ID and user.
클라이언트는 네임스페이스의 데이터 패턴에 따라 샤딩을 설정한다. 보통 샤드 ID는 객체 ID만으로 결정된다. 일부 경우, 예를 들어 네임스페이스가 멤버 수가 매우 많은 그룹을 저장하는 경우에는 샤드 ID를 객체 ID와 사용자 모두로부터 계산한다.
Zanzibar also maintains a changelog database that stores a history of tuple updates for the Watch API. The primary keys are (changelog shard ID, timestamp, unique update ID), where a changelog shard is randomly selected for each write.
Zanzibar는 또한 Watch API를 위해 튜플 갱신 이력을 저장하는 변경 로그 데이터베이스를 유지한다. 기본 키는 (변경 로그 샤드 ID, 타임스탬프, 고유 갱신 ID)이며, 변경 로그 샤드는 쓰기마다 무작위로 선택된다.
Every Zanzibar write is committed to both the tuple storage and the changelog shard in a single transaction. We designate the Spanner server hosting the changelog shard as the transaction coordinator to minimize blocking of changelog reads on pending transactions.
모든 Zanzibar 쓰기는 단일 트랜잭션으로 튜플 저장소와 변경 로그 샤드 모두에 커밋된다. 우리는 보류 중인 트랜잭션 때문에 변경 로그 읽기가 차단되는 일을 최소화하기 위해, 변경 로그 샤드를 호스팅하는 Spanner 서버를 트랜잭션 코디네이터로 지정한다.
Namespace configs are stored in a database with two tables. One table contains the configs and is keyed by namespace IDs. The other is a changelog of config updates and is keyed by commit timestamps. This structure allows a Zanzibar server to load all configs upon startup and monitor the changelog to refresh configs continuously.
네임스페이스 설정은 두 개의 테이블을 가진 데이터베이스에 저장된다. 한 테이블은 설정을 담고 있으며 네임스페이스 ID를 키로 한다. 다른 테이블은 설정 갱신의 변경 로그이며 커밋 타임스탬프를 키로 한다. 이 구조 덕분에 Zanzibar 서버는 시작 시 모든 설정을 로드하고 변경 로그를 모니터링하여 설정을 지속적으로 갱신할 수 있다.
To reduce latency, Zanzibar data is replicated to be close to our clients. Replicas exist in dozens of locations around the world, with multiple replicas per region. The 5 voting replicas are in eastern and central United States, in 3 different metropolitan areas to isolate failures but within 25 milliseconds of each other so that Paxos transactions commit quickly.
지연 시간을 줄이기 위해 Zanzibar 데이터는 클라이언트 가까이에 있도록 복제된다. 복제본은 전 세계 수십 곳에 존재하며, 리전마다 여러 개의 복제본이 있다. 5개의 투표 복제본은 미국 동부와 중부에 있으며, 장애를 격리하기 위해 서로 다른 3개 대도시권에 두되 Paxos 트랜잭션이 빠르게 커밋되도록 서로 25밀리초 이내에 위치한다.
As noted in §2.4, clients can provide zookies to ensure a minimum snapshot timestamp for request evaluation. When a zookie is not provided, the server uses a default staleness chosen to ensure that all transactions are evaluated at a timestamp that is as recent as possible without impacting latency.
§2.4에서 언급했듯이 클라이언트는 zookie를 제공하여 요청 평가에 대한 최소 스냅샷 타임스탬프를 보장할 수 있다. zookie가 제공되지 않으면 서버는 기본 오래된 정도를 사용하는데, 이는 지연 시간에 영향을 주지 않는 범위에서 모든 트랜잭션이 가능한 한 최근의 타임스탬프에서 평가되도록 선택된다.
On each read request it makes to Spanner, Zanzibar receives a hint about whether or not the data at that timestamp required an out-of-zone read and thus incurred additional latency. Each server tracks the frequency of such out-of-zone reads for data at a default staleness as well as for fresher and staler data, and uses these frequencies to compute a binomial proportion confidence interval of the probability that any given piece of data is available locally at each staleness.
Zanzibar는 Spanner에 보내는 각 읽기 요청에 대해, 해당 타임스탬프의 데이터가 존 외부 읽기를 필요로 하여 추가 지연 시간이 발생했는지 여부에 대한 힌트를 받는다. 각 서버는 기본 오래된 정도의 데이터뿐 아니라 그보다 더 최신이거나 더 오래된 데이터에 대해서도 이러한 존 외부 읽기의 빈도를 추적하고, 이 빈도를 사용하여 각 오래된 정도에서 임의의 데이터 조각이 로컬에서 사용 가능할 확률에 대한 이항 비율 신뢰 구간을 계산한다.
Upon collecting enough data, the server checks to see if each staleness value has a sufficiently low probability of incurring an out-of-zone read, and thus will be low-latency. If so, it updates the default staleness bound to the lowest “safe” value. If no known staleness values are safe, we use a two-proportion z-test to see if increasing the default will be a statistically significant amount safer. In that case, we increase the default value in the hopes of improving latency. This default staleness mechanism is purely a performance optimization. It does not violate consistency semantics because Zanzibar always respects zookies when provided.
충분한 데이터를 수집하면 서버는 각 오래된 정도 값이 존 외부 읽기를 유발할 확률이 충분히 낮아 낮은 지연 시간을 낼 수 있는지 확인한다. 그렇다면 기본 오래된 정도 한도를 가장 낮은 “안전한” 값으로 갱신한다. 알려진 오래된 정도 값 중 안전한 것이 없으면, 두 비율 z-검정을 사용하여 기본값을 늘리는 것이 통계적으로 유의미한 정도로 더 안전한지 확인한다. 그런 경우에는 지연 시간 개선을 기대하며 기본값을 늘린다. 이 기본 오래된 정도 메커니즘은 순전히 성능 최적화다. Zanzibar는 zookie가 제공되면 항상 이를 준수하므로 일관성 의미론을 위반하지 않는다.
Because changes to namespace configs can change the results of ACL evaluations, and therefore their correctness, Zanzibar chooses a single snapshot timestamp for config metadata when evaluating each client request. All aclservers in a cluster use that same timestamp for the same request, including for any subrequests that fan out from the original client request.
네임스페이스 설정의 변경은 ACL 평가 결과와 그에 따른 정확성을 바꿀 수 있으므로, Zanzibar는 각 클라이언트 요청을 평가할 때 설정 메타데이터에 대해 단일 스냅샷 타임스탬프를 선택한다. 클러스터 내 모든 aclservers는 같은 요청에 대해 같은 타임스탬프를 사용하며, 원래 클라이언트 요청에서 팬아웃되는 모든 하위 요청에도 마찬가지다.
Each server independently loads namespace configs from storage continuously as they change (§3.1.3). Therefore, each server in a cluster may have access to a different range of config timestamps due to restarts or network latency. Zanzibar must pick a timestamp that is available across all of them. To facilitate this, a monitoring job tracks the timestamp range available to every server and aggregates them, reporting a globally available range to every other server. On each incoming request the server picks a time from this range, ensuring that all servers can continue serving even if they are no longer able to read from the config storage.
각 서버는 네임스페이스 설정이 변경될 때마다 저장소에서 독립적으로 지속적으로 로드한다(§3.1.3). 따라서 클러스터 내 각 서버는 재시작이나 네트워크 지연 때문에 서로 다른 범위의 설정 타임스탬프에 접근할 수 있다. Zanzibar는 모든 서버에서 사용 가능한 타임스탬프를 골라야 한다. 이를 위해 모니터링 작업이 모든 서버에서 사용 가능한 타임스탬프 범위를 추적하고 집계하여, 전역적으로 사용 가능한 범위를 다른 모든 서버에 알린다. 서버는 들어오는 각 요청에 대해 이 범위에서 시점을 고르므로, 설정 저장소에서 더 이상 읽을 수 없게 되더라도 모든 서버가 계속 서빙할 수 있다.
Zanzibar evaluates ACL checks by converting check requests to boolean expressions. In a simple case, when there are no userset rewrite rules, checking a user against a userset ⟨object#relation⟩ can be expressed as
Zanzibar는 검사 요청을 불리언 표현식으로 변환하여 ACL 검사를 평가한다. 유저셋 재작성 규칙이 없는 단순한 경우, 사용자 를 유저셋 ⟨object#relation⟩에 대해 검사하는 것은 다음과 같이 표현할 수 있다.
Finding a valid involves evaluating membership on all indirect ACLs or groups, recursively. This kind of “pointer chasing” works well for most types of ACLs and groups, but can be expensive when indirect ACLs or groups are deep or wide. §3.2.4 explains how we handle this problem. Userset rewrite rules are also translated to boolean expressions as part of check evaluation.
유효한 를 찾으려면 모든 간접 ACL 또는 그룹에 대한 멤버십을 재귀적으로 평가해야 한다. 이러한 종류의 “포인터 추적”은 대부분의 ACL 및 그룹 유형에서 잘 작동하지만, 간접 ACL이나 그룹이 깊거나 넓으면 비용이 커질 수 있다. §3.2.4에서 이 문제를 어떻게 처리하는지 설명한다. 유저셋 재작성 규칙도 검사 평가의 일부로 불리언 표현식으로 변환된다.
To minimize check latency, we evaluate all leaf nodes of the boolean expression tree concurrently. When the outcome of one node determines the result of a subtree, evaluation of other nodes in the subtree is cancelled.
검사 지연 시간을 최소화하기 위해 우리는 불리언 표현식 트리의 모든 리프 노드를 동시에 평가한다. 한 노드의 결과가 서브트리의 결과를 결정하면 그 서브트리의 다른 노드에 대한 평가는 취소된다.
Evaluation of leaf nodes usually involves reading relation tuples from databases. We apply a pooling mechanism to group reads for the same ACL check to minimize the number of read RPCs to Spanner.
리프 노드의 평가에는 대개 데이터베이스에서 관계 튜플을 읽는 작업이 수반된다. 우리는 Spanner에 보내는 read RPC 수를 최소화하기 위해, 같은 ACL 검사에 대한 읽기를 묶는 풀링 메커니즘을 적용한다.
Recursive pointer chasing during check evaluation has difficulty maintaining low latency with groups that are deeply nested or have a large number of child groups. For selected namespaces that exhibit such structure, Zanzibar handles checks using Leopard, a specialized index that supports efficient set computation.
검사 평가 중의 재귀적 포인터 추적은 깊게 중첩되었거나 하위 그룹이 매우 많은 그룹에 대해 낮은 지연 시간을 유지하기 어렵다. 이러한 구조를 보이는 일부 선택된 네임스페이스에 대해, Zanzibar는 효율적인 집합 연산을 지원하는 특수 인덱스인 Leopard를 사용하여 검사를 처리한다.
A Leopard index represents a collection of named sets using tuples, where is an enum representing the set type and and are 64-bit integers representing the set ID and the element ID, respectively. A query evaluates an expression of union, intersection, or exclusion of named sets and returns the result set ordered by the element ID up to a specified number of results.
Leopard 인덱스는 튜플을 사용하여 이름 있는 집합의 모음을 표현하는데, 여기서 는 집합 유형을 나타내는 열거형이고 와 는 각각 집합 ID와 원소 ID를 나타내는 64비트 정수다. 쿼리는 이름 있는 집합들의 합집합, 교집합 또는 차집합으로 이루어진 표현식을 평가하고, 지정된 개수까지의 결과 집합을 원소 ID 순으로 정렬하여 반환한다.
To index and evaluate group membership, Zanzibar represents group membership with two set types, and , which we show here as functions mapping from a set ID to element IDs:
그룹 멤버십을 인덱싱하고 평가하기 위해 Zanzibar는 두 가지 집합 유형 과 으로 그룹 멤버십을 표현하며, 여기서는 이를 집합 ID에서 원소 ID로의 함수로 나타낸다.
- , where represents an ancestor group and represents a descendent group that is directly or indirectly a sub-group of the ancestor group.
- , where represents an individual user and represents a parent group in which the user is a direct member.
- . 여기서 는 조상 그룹을 나타내고 는 그 조상 그룹의 직접 또는 간접 하위 그룹인 자손 그룹을 나타낸다.
- . 여기서 는 개별 사용자를 나타내고 는 그 사용자가 직접 멤버로 속한 부모 그룹을 나타낸다.
To evaluate whether user is a member of group , we check whether
사용자 가 그룹 의 멤버인지 평가하기 위해 우리는 다음을 확인한다.
Group membership can be considered as a reachability problem in a graph, where nodes represent groups and users and edges represent direct membership. Flattening group-to-group paths allows reachability to be efficently evaluated by Leopard, though other types of denormalization can also be applied as data patterns demand.
그룹 멤버십은 노드가 그룹과 사용자를 나타내고 간선이 직접 멤버십을 나타내는 그래프에서의 도달 가능성 문제로 볼 수 있다. 그룹 간 경로를 평탄화하면 Leopard가 도달 가능성을 효율적으로 평가할 수 있으며, 데이터 패턴이 요구하는 바에 따라 다른 유형의 비정규화도 적용할 수 있다.
The Leopard system consists of three discrete parts: a serving system capable of consistent and low-latency operations across sets; an offline, periodic index building system; and an online real-time layer capable of continuously updating the serving system as tuple changes occur.
Leopard 시스템은 세 개의 개별 부분으로 구성된다. 집합에 걸쳐 일관되고 지연 시간이 낮은 연산을 수행할 수 있는 서빙 시스템, 오프라인의 주기적인 인덱스 구축 시스템, 그리고 튜플 변경이 발생할 때 서빙 시스템을 지속적으로 갱신할 수 있는 온라인 실시간 계층이다.
Index tuples are stored as ordered lists of integers in a structure such as a skip list, thus allowing for efficient union and intersections among sets. For example, evaluating the intersection between two sets, and , requires only skip-list seeks. The index is sharded by element IDs and can be distributed across multiple servers. Shards are usually served entirely from memory, but they can also be served from a mix of hot and cold data spread between memory and remote solid-state devices.
인덱스 튜플은 스킵 리스트 같은 구조에 정수의 정렬된 리스트로 저장되므로 집합 간의 합집합과 교집합을 효율적으로 계산할 수 있다. 예를 들어 두 집합 와 의 교집합을 평가하는 데는 번의 스킵 리스트 탐색만 필요하다. 인덱스는 원소 ID로 샤딩되며 여러 서버에 분산될 수 있다. 샤드는 보통 전적으로 메모리에서 서빙되지만, 메모리와 원격 솔리드 스테이트 장치에 걸쳐 분산된 핫 데이터와 콜드 데이터를 혼합하여 서빙될 수도 있다.
The offline index builder generates index shards from a snapshot of Zanzibar relation tuples and configs, and replicates the shards globally. It respects userset rewrite rules and recursively expands edges in an ACL graph to form Leopard index tuples. The Leopard servers continously watch for new shards and swap old shards with new ones when they become available.
오프라인 인덱스 빌더는 Zanzibar 관계 튜플과 설정의 스냅샷으로부터 인덱스 샤드를 생성하고, 그 샤드를 전 세계에 복제한다. 인덱스 빌더는 유저셋 재작성 규칙을 준수하며, ACL 그래프의 간선을 재귀적으로 확장하여 Leopard 인덱스 튜플을 형성한다. Leopard 서버는 새 샤드를 지속적으로 감시하다가 새 샤드가 사용 가능해지면 기존 샤드를 새 샤드로 교체한다.
The Leopard system described thus far is able to efficiently evaluate deeply and widely nested group membership, but cannot do so at a fresh and consistent snapshot due to offline index generation and shard swapping. To support consistent ACL evaluation, Leopard servers maintain an incremental layer that indexes all updates since the offline snapshot, where each update is represented by a tuple, where is the timestamp of the update and is a deletion marker. Updates with timestamps less than or equal to the query timestamp are merged on top of the offline index during query processing.
지금까지 설명한 Leopard 시스템은 깊고 넓게 중첩된 그룹 멤버십을 효율적으로 평가할 수 있지만, 오프라인 인덱스 생성과 샤드 교체 때문에 최신의 일관된 스냅샷에서는 그렇게 할 수 없다. 일관된 ACL 평가를 지원하기 위해 Leopard 서버는 오프라인 스냅샷 이후의 모든 갱신을 인덱싱하는 증분 계층을 유지한다. 각 갱신은 튜플로 표현되며, 여기서 는 갱신의 타임스탬프이고 는 삭제 표시다. 쿼리 처리 중에는 쿼리 타임스탬프 이하의 타임스탬프를 가진 갱신이 오프라인 인덱스 위에 병합된다.
To maintain the incremental layer, the Leopard incremental indexer calls Zanzibar’s Watch API to receive a temporally ordered stream of Zanzibar tuple modifications and transforms the updates into a temporally ordered stream of Leopard tuple additions, updates, and deletions. Generating updates for the tuples requires the incremental indexer to maintain group-to-group membership for denormalizing the effects of a relation tuple update to potentially multiple index updates.
증분 계층을 유지하기 위해 Leopard 증분 인덱서는 Zanzibar의 Watch API를 호출하여 시간 순으로 정렬된 Zanzibar 튜플 수정 스트림을 받고, 그 갱신을 시간 순으로 정렬된 Leopard 튜플 추가, 갱신, 삭제 스트림으로 변환한다. 튜플에 대한 갱신을 생성하려면, 증분 인덱서는 하나의 관계 튜플 갱신이 미치는 영향을 잠재적으로 여러 개의 인덱스 갱신으로 비정규화하기 위해 그룹 간 멤버십을 유지해야 한다.
In practice, a single Zanzibar tuple addition or deletion may yield potentially tens of thousands of discrete Leopard tuple events. Each Leopard serving instance receives the complete stream of these Zanzibar tuple changes through the Watch API. The Leopard serving system is designed to continuously ingest this stream and update its various posting lists with minimal impact to query serving.
실제로 Zanzibar 튜플 하나의 추가나 삭제는 잠재적으로 수만 개의 개별 Leopard 튜플 이벤트를 낳을 수 있다. 각 Leopard 서빙 인스턴스는 Watch API를 통해 이러한 Zanzibar 튜플 변경의 전체 스트림을 받는다. Leopard 서빙 시스템은 쿼리 서빙에 미치는 영향을 최소화하면서 이 스트림을 지속적으로 수집하고 다양한 포스팅 리스트를 갱신하도록 설계되었다.
The workload of ACL reads and checks is often bursty and subject to hot spots. For example, answering a search query requires conducting ACL checks for all candidate results, whose ACLs often share common groups or indirect ACLs. To facilitate consistency, Zanzibar avoids storage denormalization and relies only on normalized data (except for the cases described in §3.2.4). With normalized data, hot spots on common ACLs (e.g., popular groups) may overload the underlying database servers. We found the handling of hot spots to be the most critical frontier in our pursuit of low latency and high availability.
ACL 읽기와 검사 워크로드는 버스트성이 강하고 핫스팟이 생기기 쉽다. 예를 들어 검색 쿼리에 응답하려면 모든 후보 결과에 대해 ACL 검사를 수행해야 하는데, 이들의 ACL은 흔히 공통 그룹이나 간접 ACL을 공유한다. 일관성을 용이하게 하기 위해 Zanzibar는 저장소 비정규화를 피하고 정규화된 데이터에만 의존한다(§3.2.4에서 설명한 경우는 제외). 정규화된 데이터에서는 공통 ACL(예를 들어 인기 있는 그룹)의 핫스팟이 하부 데이터베이스 서버에 과부하를 일으킬 수 있다. 우리는 핫스팟 처리가 낮은 지연 시간과 높은 가용성을 추구하는 데 있어 가장 중요한 최전선임을 알게 되었다.
Zanzibar servers in each cluster form a distributed cache for both reads and check evaluations, including intermediate check results evaluated during pointer chasing. Cache entries are distributed across Zanzibar servers with consistent hashing [20]. To process checks or reads, we fan out requests to the corresponding Zanzibar servers via an internal RPC interface. To minimize the number of internal RPCs, for most namespaces we compute the forwarding key from the object ID, since processing a check on ⟨object#relation⟩ often involves indirect ACL checks on other relations of the same object and reading relation tuples of the object. These checks and reads can be processed by the same server since they share the same forwarding key with the parent check request. To handle hot forwarding keys, we cache results at both the caller and the callee of internal RPCs, effectively forming cache trees. We also use Slicer [12] to help distribute hot keys to multiple servers.
각 클러스터의 Zanzibar 서버들은 읽기와 검사 평가 모두를 위한 분산 캐시를 형성하며, 여기에는 포인터 추적 중에 평가된 중간 검사 결과도 포함된다. 캐시 항목은 일관된 해싱 [20]으로 Zanzibar 서버들에 분산된다. 검사나 읽기를 처리하기 위해 우리는 내부 RPC 인터페이스를 통해 해당 Zanzibar 서버로 요청을 팬아웃한다. 내부 RPC 수를 최소화하기 위해 대부분의 네임스페이스에서는 객체 ID로부터 포워딩 키를 계산한다. ⟨object#relation⟩에 대한 검사를 처리하는 데에는 흔히 같은 객체의 다른 관계에 대한 간접 ACL 검사와 그 객체의 관계 튜플 읽기가 수반되기 때문이다. 이러한 검사와 읽기는 부모 검사 요청과 같은 포워딩 키를 공유하므로 같은 서버에서 처리될 수 있다. 핫 포워딩 키를 처리하기 위해 우리는 내부 RPC의 호출자와 피호출자 양쪽에서 결과를 캐싱하여 사실상 캐시 트리를 형성한다. 또한 Slicer [12]를 사용하여 핫 키를 여러 서버에 분산하는 데 도움을 받는다.
We avoid reusing results evaluated from a different snapshot by encoding snapshot timestamps in cache keys. We choose evaluation timestamps rounded up to a coarse granularity, such as one or ten seconds, while respecting staleness constraints from request zookies. This timestamp quantization allows the vast majority of recent checks and reads to be evaluated at the same timestamps and to share cache results, despite having microsecond-resolution timestamps in cache keys. It is worth noting that rounding up timestamps does not affect Zanzibar’s consistency properties, since Spanner ensures that a snapshot read at timestamp will observe all writes up to —this holds even if is in the future, in which case the read will wait until TrueTime has moved past .
우리는 스냅샷 타임스탬프를 캐시 키에 인코딩하여 다른 스냅샷에서 평가된 결과를 재사용하지 않도록 한다. 요청 zookie의 오래된 정도 제약을 준수하면서, 평가 타임스탬프를 1초나 10초 같은 거친 단위로 올림하여 선택한다. 이러한 타임스탬프 양자화 덕분에 캐시 키에 마이크로초 해상도의 타임스탬프가 들어 있음에도 최근 검사와 읽기의 대다수가 같은 타임스탬프에서 평가되어 캐시 결과를 공유할 수 있다. 타임스탬프를 올림해도 Zanzibar의 일관성 속성에는 영향을 주지 않는다는 점에 주목할 만하다. Spanner는 타임스탬프 에서의 스냅샷 읽기가 까지의 모든 쓰기를 관측하도록 보장하기 때문이다. 이는 가 미래인 경우에도 성립하며, 그 경우 읽기는 TrueTime이 를 지날 때까지 기다린다.
To handle the “cache stampede” problem [3], where concurrent requests create flash hot spots before the cache is populated with results, we maintain a lock table on each server to track outstanding reads and checks. Among requests sharing the same cache key only one request will begin processing; the rest block until the cache is populated.
캐시가 결과로 채워지기 전에 동시 요청들이 순간적인 핫스팟을 만드는 “캐시 스탬피드” 문제 [3]를 처리하기 위해, 우리는 각 서버에 락 테이블을 유지하여 처리 중인 읽기와 검사를 추적한다. 같은 캐시 키를 공유하는 요청 중에서는 하나의 요청만 처리를 시작하고, 나머지는 캐시가 채워질 때까지 블록된다.
We can effectively handle the vast majority of hot spots with distributed caches and lock tables. Over time we made the following two improvements.
우리는 분산 캐시와 락 테이블로 핫스팟의 대다수를 효과적으로 처리할 수 있다. 시간이 지나면서 우리는 다음 두 가지 개선을 했다.
First, direct membership checks of a user for an object and relation (i.e. ⟨object#relation@user⟩) are usually handled by a single relation tuple lookup. However, occasionally a very popular object invites many concurrent checks for different users, causing a hot spot on the storage server hosting relation tuples for the object. To avoid these hot spots, we read and cache all relation tuples of ⟨object#relation⟩ for the hot object, trading read bandwidth for cacheability. We dynamically detect hot objects to apply this method to by tracking the number of outstanding reads on each object.
첫째, 객체와 관계에 대한 사용자의 직접 멤버십 검사(즉 ⟨object#relation@user⟩)는 보통 관계 튜플 조회 한 번으로 처리된다. 그러나 가끔 매우 인기 있는 객체에 서로 다른 사용자에 대한 동시 검사가 많이 몰려, 그 객체의 관계 튜플을 호스팅하는 저장소 서버에 핫스팟이 생긴다. 이러한 핫스팟을 피하기 위해 우리는 핫 객체에 대해 ⟨object#relation⟩의 관계 튜플을 모두 읽어 캐싱하며, 읽기 대역폭을 내주는 대신 캐시 가능성을 얻는다. 각 객체에 대해 처리 중인 읽기 수를 추적하여 이 방법을 적용할 핫 객체를 동적으로 감지한다.
Second, indirect ACL checks are frequently cancelled when the result of the parent ACL check is already determined. This leaves the cache key unpopulated. While eager cancellation reduces resource usage significantly, it negatively affects latency of concurrent requests that are blocked by the lock table entry. To prevent this latency impact, we delay eager cancellation when there are waiters on the corresponding lock table entry.
둘째, 간접 ACL 검사는 부모 ACL 검사의 결과가 이미 결정되면 자주 취소된다. 이 경우 캐시 키가 채워지지 않은 채로 남는다. 조기 취소는 자원 사용을 크게 줄이지만, 락 테이블 항목에 의해 블록된 동시 요청의 지연 시간에는 부정적인 영향을 미친다. 이러한 지연 시간 영향을 방지하기 위해, 해당 락 테이블 항목에 대기자가 있으면 조기 취소를 지연시킨다.
Performance isolation is indispensable for shared services targeting low latency and high availability. If Zanzibar or one of its clients occasionally fails to provision enough resources to handle an unexpected usage pattern, the following isolation mechanisms ensure that performance problems are isolated to the problematic use case and do not adversely affect other clients.
성능 격리는 낮은 지연 시간과 높은 가용성을 목표로 하는 공유 서비스에 필수적이다. Zanzibar나 그 클라이언트 중 하나가 예상치 못한 사용 패턴을 처리하기에 충분한 자원을 가끔 확보하지 못하더라도, 다음의 격리 메커니즘은 성능 문제가 문제를 일으킨 사용 사례로 격리되어 다른 클라이언트에 악영향을 주지 않도록 보장한다.
First, to ensure proper allocation of CPU capacity, Zanzibar measures the cost of each RPC in terms of generic cpu-seconds, a hardware-agnostic metric. Each client has a global limit on maximum CPU usage per second; its RPCs will be throttled if it exceeds the limit and there is no spare capacity in the overall system.
첫째, CPU 용량을 적절히 할당하기 위해 Zanzibar는 각 RPC의 비용을 하드웨어에 무관한 지표인 일반화된 cpu-seconds 단위로 측정한다. 각 클라이언트에는 초당 최대 CPU 사용량에 대한 글로벌 한도가 있으며, 클라이언트가 한도를 초과하고 동시에 전체 시스템에 여유 용량이 없으면 그 클라이언트의 RPC가 스로틀링된다.
Each Zanzibar server also limits the total number of outstanding RPCs to control its memory usage. Likewise it limits the number of oustanding RPCs per client.
각 Zanzibar 서버는 메모리 사용량을 제어하기 위해 처리 중인 RPC의 총수도 제한한다. 마찬가지로 클라이언트별로 처리 중인 RPC 수도 제한한다.
Zanzibar further limits the maximum number of concurrent reads per (object, client) and per client on each Spanner server. This ensures that no single object or client can monopolize a Spanner server.
Zanzibar는 더 나아가 각 Spanner 서버에서 (객체, 클라이언트)별 및 클라이언트별 최대 동시 읽기 수를 제한한다. 이를 통해 어떤 단일 객체나 클라이언트도 Spanner 서버를 독점할 수 없게 된다.
Finally, we use different lock table keys for requests from different clients to prevent any throttling that Spanner applies to one client from affecting other clients.
마지막으로, Spanner가 한 클라이언트에 적용하는 스로틀링이 다른 클라이언트에 영향을 주지 않도록 서로 다른 클라이언트의 요청에 서로 다른 락 테이블 키를 사용한다.
Zanzibar’s distributed processing requires measures to accommodate slow tasks. For calls to Spanner and to the Leopard index we rely on request hedging [16] (i.e. we send the same request to multiple servers, use whichever response comes back first, and cancel the other requests). To reduce round-trip times, we try to place at least two replicas of these backend services in every geographical region where we have Zanzibar servers. To avoid unnecessarily multiplying load, we first send one request and defer sending hedged requests until the initial request is known to be slow.
Zanzibar의 분산 처리에는 느린 작업에 대응하기 위한 조치가 필요하다. Spanner와 Leopard 인덱스에 대한 호출에는 요청 헤징 [16]을 활용한다(즉, 같은 요청을 여러 서버에 보내고 먼저 돌아오는 응답을 사용하며 나머지 요청은 취소한다). 왕복 시간을 줄이기 위해 Zanzibar 서버가 있는 모든 지리적 리전에 이러한 백엔드 서비스의 복제본을 적어도 두 개 배치하려고 한다. 불필요하게 부하를 늘리지 않도록, 먼저 하나의 요청을 보내고 초기 요청이 느리다는 것이 확인될 때까지 헤지 요청의 전송을 미룬다.
To determine the appropriate hedging delay threshold, each server maintains a delay estimator that dynamically computes an Nth percentile latency based on recent measurements. This mechanism allows us to limit the additional traffic incurred by hedging to a small fraction of total traffic.
적절한 헤징 지연 임계값을 결정하기 위해, 각 서버는 최근 측정값을 기반으로 N번째 백분위수 지연 시간을 동적으로 계산하는 지연 추정기를 유지한다. 이 메커니즘 덕분에 헤징으로 인한 추가 트래픽을 전체 트래픽의 작은 비율로 제한할 수 있다.
Effective hedging requires the requests to have similar costs. In the case of Zanzibar’s authorization checks, some checks are inherently more time-consuming than others because they require more work. Hedging check requests would result in duplicating the most expensive workloads and, ironically, worsening latency. Therefore we do not hedge requests between Zanzibar servers, but rely on the previously discussed sharding among multiple replicas and on monitoring mechanisms to detect and avoid slow servers.
효과적인 헤징을 위해서는 요청들의 비용이 비슷해야 한다. Zanzibar의 인가 검사의 경우, 일부 검사는 더 많은 작업을 필요로 하기 때문에 본질적으로 다른 검사보다 시간이 더 걸린다. 검사 요청을 헤징하면 가장 비싼 워크로드가 중복되어 역설적으로 지연 시간이 악화된다. 따라서 우리는 Zanzibar 서버 간의 요청은 헤징하지 않고, 앞서 논의한 여러 복제본 간의 샤딩과 모니터링 메커니즘에 의존하여 느린 서버를 감지하고 피한다.
Zanzibar has been in production use for more than 5 years. Throughout that time, the number of clients using Zanzibar and the load they place on Zanzibar have grown steadily. This section discusses our experience operating Zanzibar as a globally distributed authorization system.
Zanzibar는 5년 넘게 프로덕션에서 사용되어 왔다. 그 기간 내내 Zanzibar를 사용하는 클라이언트 수와 그들이 Zanzibar에 가하는 부하는 꾸준히 증가했다. 이 절에서는 Zanzibar를 글로벌 분산 인가 시스템으로 운영한 경험을 논의한다.
Zanzibar manages more than 1,500 namespaces defined by hundreds of client applications. The size of a namespace configuration file serves as a rough measure of the complexity of the access control policy implemented by that namespace. These configuration files range from tens of lines to thousands of lines, with the median near 500 lines.
Zanzibar는 수백 개의 클라이언트 애플리케이션이 정의한 1,500개 이상의 네임스페이스를 관리한다. 네임스페이스 설정 파일의 크기는 그 네임스페이스가 구현하는 접근 제어 정책의 복잡도를 대략적으로 나타내는 척도가 된다. 이러한 설정 파일은 수십 줄에서 수천 줄에 이르며, 중앙값은 500줄 가까이 된다.
These namespaces contain more than 2 trillion relation tuples that occupy close to 100 terabytes. The number of tuples per namespace ranges over many orders of magnitude, from tens to a trillion, with the median near 15,000. This data is fully replicated in more than 30 locations around the world to maintain both proximity to users and high availability.
이 네임스페이스들에는 100테라바이트에 가까운 공간을 차지하는 2조 개 이상의 관계 튜플이 들어 있다. 네임스페이스당 튜플 수는 수십 개에서 1조 개까지 여러 자릿수에 걸쳐 분포하며, 중앙값은 15,000개 가까이 된다. 이 데이터는 사용자와의 근접성과 높은 가용성을 모두 유지하기 위해 전 세계 30곳 이상에 완전히 복제된다.
Zanzibar serves more than 10 million client queries per second (QPS). Over a sample 7-day period in December 2018, Check requests peak at roughly 4.2M QPS, Read at 8.2M, Expand at 760K, and Write at 25K. Queries that read data are thus two orders of magnitude more frequent than those that write data.
Zanzibar는 초당 1,000만 건 이상의 클라이언트 쿼리(QPS)를 처리한다. 2018년 12월의 7일간 표본 기간 동안 Check 요청은 최대 약 4.2M QPS, Read는 8.2M, Expand는 760K, Write는 25K에 달했다. 따라서 데이터를 읽는 쿼리가 데이터를 쓰는 쿼리보다 두 자릿수 더 빈번하다.
Zanzibar distributes this load across more than 10,000 servers organized in several dozen clusters around the world. The number of servers per cluster ranges from fewer than 100 to more than 1,000, with the median near 500. Clusters are sized in proportion to load in their geographic regions.
Zanzibar는 이 부하를 전 세계 수십 개 클러스터로 구성된 10,000대 이상의 서버에 분산한다. 클러스터당 서버 수는 100대 미만에서 1,000대 이상에 이르며, 중앙값은 500대 가까이 된다. 클러스터 크기는 해당 지리적 리전의 부하에 비례하여 정해진다.
We divide requests into two categories according to the required data freshness, which can have a large impact on latency and availability of the requests. Specifically, Check, Read, and Expand requests carry zookies to specify lower bounds on evaluation timestamps. When a zookie timestamp is higher than that of the most recent data replicated to the region, the storage reads require cross-region round trips to the leader replica to retrieve fresher data. As our storage is configured with replication heartbeats with 8-second intervals, we divide our requests into two categories: Safe requests have zookies more than 10 seconds old and can be served within the region most of time, while Recent requests have zookies less than 10 seconds old and often require inter-region round trips. We report separate statistics for each.
우리는 요청을 필요한 데이터 최신성에 따라 두 범주로 나눈다. 데이터 최신성은 요청의 지연 시간과 가용성에 큰 영향을 미칠 수 있다. 구체적으로 Check, Read, Expand 요청은 평가 타임스탬프의 하한을 지정하기 위해 zookie를 포함한다. zookie 타임스탬프가 해당 리전에 복제된 가장 최근 데이터의 타임스탬프보다 높으면, 저장소 읽기는 더 최신 데이터를 가져오기 위해 리더 복제본까지 리전 간 왕복을 해야 한다. 저장소는 8초 간격의 복제 하트비트로 설정되어 있으므로, 우리는 요청을 두 범주로 나눈다. Safe 요청은 10초보다 오래된 zookie를 가지며 대부분 리전 내에서 처리될 수 있는 반면, Recent 요청은 10초 미만의 zookie를 가지며 흔히 리전 간 왕복이 필요하다. 각각에 대해 별도의 통계를 보고한다.
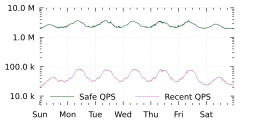
Figure 3: Rate of Check Safe and Check Recent requests over a 7-day period in December 2018.
그림 3: 2018년 12월의 7일간 Check Safe 요청과 Check Recent 요청의 요청률.
Figure 3 shows the rate of Check Safe and Check Recent requests over 7 days. Both exhibit a diurnal cycle. The rate of Safe requests is about two orders of magnitude larger than that of Recent requests, which allows Zanzibar to serve the vast majority of ACL checks locally.
그림 3은 7일간의 Check Safe 요청과 Check Recent 요청의 요청률을 보여 준다. 둘 다 일주기(diurnal cycle)를 보인다. Safe 요청의 요청률은 Recent 요청의 요청률보다 약 두 자릿수 크며, 덕분에 Zanzibar는 ACL 검사의 대다수를 로컬에서 처리할 수 있다.
Zanzibar’s latency budget is generally a small fraction of the few hundreds of milliseconds of total response time that its clients must provide to be viable interactive services. Consider for example a client that performs authorization checks on multiple documents before it can show the results of a search on those documents.
Zanzibar의 지연 시간 예산은 일반적으로 클라이언트가 실용적인 대화형 서비스가 되기 위해 제공해야 하는 수백 밀리초의 전체 응답 시간 중 작은 일부다. 예를 들어 여러 문서에 대한 검색 결과를 보여 주기 전에 그 문서들에 대해 인가 검사를 수행하는 클라이언트를 생각해 보자.
We measure latency on the server side using live traffic because (1) latency is heavily influenced by our caching and de-duplication mechanisms so that it is only realistically reflected by live traffic, and (2) accurately measuring latency from clients requires well-behaving clients. Provisioning of client jobs is outside of Zanzibar’s control and sometimes client jobs are overloaded.
우리는 실제 트래픽을 사용하여 서버 측에서 지연 시간을 측정한다. 그 이유는 (1) 지연 시간이 캐싱과 중복 제거 메커니즘의 영향을 크게 받아 실제 트래픽에서만 현실적으로 반영되고, (2) 클라이언트에서 지연 시간을 정확히 측정하려면 클라이언트가 올바르게 동작해야 하기 때문이다. 클라이언트 작업의 자원 프로비저닝은 Zanzibar가 통제할 수 없는 영역이며, 때때로 클라이언트 작업은 과부하 상태가 된다.
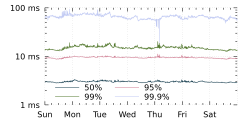
Figure 4: Latency of Check Safe responses at different percentiles over a 7-day period in December 2018.
그림 4: 2018년 12월의 7일간 백분위수별 Check Safe 응답 지연 시간.
Figure 4 shows the latency of Check Safe responses over 7 days. At the 50th, 95th, 99th, and 99.9th percentiles it peaks at roughly 3, 11, 20, and 93 msec, respectively. This performance meets our latency goals for an operation that is frequently in the critical path of user interactions.
그림 4는 7일간 Check Safe 응답의 지연 시간을 보여 준다. 50번째, 95번째, 99번째, 99.9번째 백분위수에서 최대값은 각각 약 3, 11, 20, 93 msec이다. 이 성능은 사용자 상호작용의 임계 경로에 자주 놓이는 작업에 대한 우리의 지연 시간 목표를 충족한다.
Table 2 summarizes the latency distributions of Check, Read, Expand, and Write responses over the same 7 days. As intended, the more frequently used Safe versions of Check, Read, and Expand are significantly faster than the less frequently used Recent versions. Writes are the least frequently used of all the APIs, and the slowest because they always require distributed coordination among Spanner servers.
표 2는 같은 7일간 Check, Read, Expand, Write 응답의 지연 시간 분포를 요약한다. 의도한 대로, 더 자주 사용되는 Safe 버전의 Check, Read, Expand는 덜 자주 사용되는 Recent 버전보다 훨씬 빠르다. Write는 모든 API 중 가장 드물게 사용되며, 항상 Spanner 서버 간의 분산 조율이 필요하므로 가장 느리다.
Table 2: Mean and standard deviation of RPC response latency over a 7-day period in December 2018.
표 2: 2018년 12월의 7일간 RPC 응답 지연 시간의 평균과 표준편차.
We define availability as the fraction of “qualified” RPCs the service answers successfully within latency thresholds: 5 seconds for a Safe request, and 15 seconds for a Recent request as leader re-election in Spanner may take up to 10 seconds. For an RPC to be qualified, the request must be well-formed and have a deadline longer than the latency threshold. In addition, the client must stay within its resource quota.
우리는 가용성을 서비스가 지연 시간 임계값 이내에 성공적으로 응답한 “적격” RPC의 비율로 정의한다. 임계값은 Safe 요청의 경우 5초, Recent 요청의 경우 15초인데, Spanner의 리더 재선출에 최대 10초가 걸릴 수 있기 때문이다. RPC가 적격이 되려면 요청의 형식이 올바르고 지연 시간 임계값보다 긴 데드라인을 가져야 한다. 또한 클라이언트는 자신의 자원 할당량 이내에 머물러야 한다.
For these reasons, we cannot measure availability directly with live traffic, as our clients sometimes send RPCs with short deadlines or cancel their in-progress RPCs. Instead, we sample a small fraction of valid requests from live traffic and replay them later with our own probers. When replaying the requests, we set the timeout to be longer than the availability threshold. We also adjust the request zookie, if one is specified, so that the relative age of the zookie remains the same as when the request was received in the live traffic. Finally, we run 3 probers per cluster and exclude outliers to eliminate false alarms caused by rare prober failures.
이러한 이유로 클라이언트가 때때로 짧은 데드라인으로 RPC를 보내거나 진행 중인 RPC를 취소하기 때문에, 우리는 실제 트래픽으로 가용성을 직접 측정할 수 없다. 대신 실제 트래픽에서 유효한 요청의 작은 일부를 샘플링하여 나중에 자체 프로버로 재생한다. 요청을 재생할 때는 타임아웃을 가용성 임계값보다 길게 설정한다. 또한 요청 zookie가 지정되어 있으면, zookie의 상대적 경과 시간이 실제 트래픽에서 요청을 받았을 때와 같게 유지되도록 조정한다. 마지막으로 클러스터당 3개의 프로버를 실행하고 이상값을 제외하여, 드문 프로버 장애로 인한 오경보를 제거한다.
To compute availability, we aggregate success ratios over 90-day windows averaged across clusters. Figure 5 shows Zanzibar’s availability as measured by these probers. Availability has remained above 99.999% over the past 3 years of operation at Google. In other words, for every quarter, Zanzibar has less than 2 minutes of global downtime and fewer than 13 minutes when the global error ratio exceeds 10%.
가용성을 계산하기 위해 우리는 90일 단위 기간에 걸친 성공률을 집계하여 클러스터 전체에 대해 평균한다. 그림 5는 이러한 프로버로 측정한 Zanzibar의 가용성을 보여 준다. 가용성은 Google에서 운영된 지난 3년 동안 99.999% 이상을 유지해 왔다. 다시 말해 매 분기 Zanzibar의 글로벌 다운타임은 2분 미만이며, 글로벌 오류율이 10%를 초과하는 시간은 13분 미만이다.
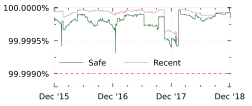
Figure 5: Zanzibar’s availability over the past three years has remained above 99.999%.
그림 5: 지난 3년간 Zanzibar의 가용성은 99.999% 이상을 유지해 왔다.
Zanzibar servers delegate checks and reads to each other based on consistent hashing, and both the caller and the callee sides of the delegated operations cache the results to prevent hot spots (§3.2.5). At peak, Zanzibar handles 22 million internal “delegated” RPCs per second, split about evenly between reads and checks. In-memory caching handles approximately 200 million lookups per second at peak, 150 million from checks and 50 million from reads. Caching for checks has a 10% hit rate on the delegate’s side, with an additional 12% saved by the lock table. Meanwhile, caching on the delegator’s side has a 2% hit rate with an additional 3% from the lock table. While these hit rates appear low, they prevent 500K internal RPCs per second from creating hot spots.
Zanzibar 서버는 일관된 해싱에 기반하여 검사와 읽기를 서로에게 위임하며, 위임된 작업의 호출자와 피호출자 양쪽 모두 핫스팟을 방지하기 위해 결과를 캐싱한다(§3.2.5). 피크 시 Zanzibar는 초당 2,200만 건의 내부 “위임” RPC를 처리하며, 읽기와 검사가 대략 절반씩을 차지한다. 인메모리 캐싱은 피크 시 초당 약 2억 건의 조회를 처리하는데, 그중 1억 5,000만 건은 검사에서, 5,000만 건은 읽기에서 나온다. 검사에 대한 캐싱은 위임받는 쪽(delegate)에서 10%의 적중률을 보이며, 락 테이블로 추가로 12%를 절약한다. 한편 위임하는 쪽(delegator)의 캐싱은 2%의 적중률을 보이며, 락 테이블로 추가로 3%를 절약한다. 이 적중률은 낮아 보이지만, 초당 50만 건의 내부 RPC가 핫스팟을 만드는 것을 막는다.
Delegated reads see higher hit rates on the delegate’s side—24% on the cache and 9% on the lock table—but the delegator’s cache is hit less than 1% of the time. For super-hot groups, Zanzibar further optimizes by reading and caching the full set of members in advance—this happens for 0.1% of groups but further prevents hot spots.
위임된 읽기는 위임받는 쪽에서 더 높은 적중률을 보이지만(캐시에서 24%, 락 테이블에서 9%), 위임하는 쪽의 캐시 적중률은 1% 미만이다. 매우 뜨거운(super-hot) 그룹에 대해서는 Zanzibar가 멤버 전체 집합을 미리 읽어 캐싱하는 추가 최적화를 수행한다. 이는 그룹의 0.1%에 대해 일어나지만 핫스팟을 더욱 방지한다.
This caching, along with aggressive pooling of read requests, allows Zanzibar to issue only 20 million read RPCs per second to Spanner. The median of these requests reads 1.5 rows per RPC, but at the 99th percentile they each read close to 1 thousand rows.
이러한 캐싱과 공격적인 읽기 요청 풀링 덕분에 Zanzibar는 Spanner에 초당 2,000만 건의 read RPC만 보낸다. 이 요청들의 중앙값은 RPC당 1.5개 행을 읽지만, 99번째 백분위수에서는 각각 1,000개에 가까운 행을 읽는다.
Zanzibar’s Spanner reads take 0.5 msec at the median, and 2 msec at the 95th percentile. We find that 1% of Spanner reads, or 200K reads per second, benefit from hedging. We note that Zanzibar uses an instance of Spanner that runs internally to Google, not an instance of Cloud Spanner [6].
Zanzibar의 Spanner 읽기는 중앙값에서 0.5 msec, 95번째 백분위수에서 2 msec가 걸린다. Spanner 읽기의 1%, 즉 초당 20만 건의 읽기가 헤징의 이점을 얻는 것으로 나타났다. Zanzibar는 Cloud Spanner [6]의 인스턴스가 아니라 Google 내부에서 실행되는 Spanner 인스턴스를 사용한다는 점을 밝혀 둔다.
The Leopard index is performing 1.56M QPS at the median, or 2.22M QPS at the 99th percentile, based on data aggregated over 7 days. Over the same 7 days, Leopard servers respond in fewer than 150 μsec at the median, or under 1 msec at the 99th percentile. Leopard’s incremental layer during those 7 days writes roughly 500 index updates per second at the median, and approximately 1.5K updates per second at the 99th percentile.
7일간 집계한 데이터에 따르면 Leopard 인덱스는 중앙값에서 1.56M QPS, 99번째 백분위수에서 2.22M QPS를 처리하고 있다. 같은 7일 동안 Leopard 서버는 중앙값에서 150 μsec 미만, 99번째 백분위수에서 1 msec 미만으로 응답한다. 그 7일 동안 Leopard의 증분 계층은 중앙값에서 초당 약 500건, 99번째 백분위수에서 초당 약 1.5K건의 인덱스 갱신을 기록한다.
Zanzibar has evolved to meet the varied and heavy demands of a growing set of clients, including Google Calendar, Google Cloud, Google Drive, Google Maps, Google Photos, and YouTube. This section highlights lessons learned from this experience.
Zanzibar는 Google Calendar, Google Cloud, Google Drive, Google Maps, Google Photos, YouTube를 포함하여 점점 늘어나는 클라이언트의 다양하고 막대한 요구를 충족하도록 발전해 왔다. 이 절에서는 이 경험에서 얻은 교훈을 조명한다.
One common theme has been the importance of flexibility to accommodate differences between clients. For example:
공통된 주제 하나는 클라이언트 간의 차이를 수용하기 위한 유연성의 중요성이었다. 예를 들면 다음과 같다.
- Access control patterns vary widely: Over time we have added features to support specific clients. For instance, we added
computed_usersetto allow inferring an object’s owner ID from the object ID prefix, which reduces space requirements for clients such as Drive and Photos that manage many private objects. Similarly, we addedtuple_to_usersetto represent object hierarchy with only one relation tuple per hop. The benefits are both space reduction and flexibility—it allows clients such as Cloud both to express ACL inheritance compactly and to change ACL inheritance rules without having to update large numbers of tuples. See §2.3.1. - Freshness requirements are often but not always loose: Clients often allow unspecified, moderate staleness during ACL evaluation, but sometimes require more precisely specified freshness. We designed our zookie protocol around this property so that we can serve most requests from a default, already replicated snapshot, while allowing clients to bound the staleness when needed. We also tuned the granularity of our snapshot timestamps to match clients’ freshness requirements. The resulting coarse timestamp quanta allow us to perform the majority of authorization checks on a small number of snapshots, thus greatly reducing the frequency of database reads. See §3.2.1.
- 접근 제어 패턴은 매우 다양하다: 시간이 지나면서 우리는 특정 클라이언트를 지원하기 위한 기능을 추가했다. 예를 들어 객체 ID 접두사로부터 객체의 소유자 ID를 추론할 수 있도록
computed_userset을 추가했는데, 이는 Drive나 Photos처럼 비공개 객체를 많이 관리하는 클라이언트의 공간 요구량을 줄여 준다. 마찬가지로 홉당 관계 튜플 하나만으로 객체 계층 구조를 표현하기 위해tuple_to_userset을 추가했다. 이점은 공간 절감과 유연성 두 가지다. 이를 통해 Cloud 같은 클라이언트는 ACL 상속을 간결하게 표현할 수 있고, 많은 수의 튜플을 갱신하지 않고도 ACL 상속 규칙을 변경할 수 있다. §2.3.1을 참조하라. - 최신성 요구 사항은 흔히 느슨하지만 항상 그런 것은 아니다: 클라이언트는 ACL 평가 중에 명시되지 않은 적당한 수준의 오래됨을 허용하는 경우가 많지만, 때로는 더 정밀하게 지정된 최신성을 요구한다. 우리는 이 속성을 중심으로 zookie 프로토콜을 설계하여, 대부분의 요청은 이미 복제된 기본 스냅샷에서 처리하면서도 필요할 때는 클라이언트가 오래된 정도를 제한할 수 있도록 했다. 또한 클라이언트의 최신성 요구 사항에 맞게 스냅샷 타임스탬프의 단위를 조정했다. 그 결과로 얻은 거친 타임스탬프 단위 덕분에 인가 검사의 대부분을 적은 수의 스냅샷에서 수행할 수 있어 데이터베이스 읽기 빈도가 크게 줄어든다. §3.2.1을 참조하라.
Another theme has been the need to add performance optimizations to support client behaviors observed in production. For example:
또 다른 주제는 프로덕션에서 관측된 클라이언트 동작을 지원하기 위해 성능 최적화를 추가할 필요성이었다. 예를 들면 다음과 같다.
- Request hedging is key to reducing tail latency: Clients that offer search capabilities to their users, such as Drive, often issue tens to hundreds of authorization checks to serve a single set of search results. We introduced hedging of Spanner and Leopard requests to prevent an occasional slow operation from slowing the overall user interaction. See §3.2.7.
- Hot-spot mitigation is critical for high availability: Some workloads create hot spots in ACL data that can overwhelm the underlying database servers. A common pattern is a burst of ACL checks for an object that is indirectly referenced by the ACLs for many different objects. Specific instances arise from the search use case mentioned above, where the documents in the search indirectly share ACLs for a large social or work group, and Cloud use cases where many objects indirectly share ACLs for the same object high in a hierarchy. Zanzibar handles most hot spots with general mechanisms such as its distributed cache and lock table, but we have found the need to optimize specific uses cases. For example, we added cache prefetching of all relation tuples for a hot object. We also delayed cancellation of secondary ACL checks when there are concurrent requests for the same ACL data. See §3.2.5.
- Performance isolation is indispensable to protect against misbehaving clients: Even with hot-spot mitigation measures, unexpected and sometimes unintended client behaviors could still overload our system or its underlying infrastructure. Examples include when clients launch new features that prove unexpectedly popular or exercise Zanzibar in unintended ways. Over time we have added isolation safeguards to ensure that there are no cascading failures between clients or between objects of the same client. These safeguards include fine-grained cost accounting, quotas, and throttling. See §3.2.6.
- 요청 헤징은 꼬리 지연 시간 감소의 핵심이다: Drive처럼 사용자에게 검색 기능을 제공하는 클라이언트는 한 묶음의 검색 결과를 제공하기 위해 흔히 수십에서 수백 건의 인가 검사를 보낸다. 우리는 가끔 발생하는 느린 작업이 전체 사용자 상호작용을 느리게 만들지 않도록 Spanner와 Leopard 요청에 헤징을 도입했다. §3.2.7을 참조하라.
- 핫스팟 완화는 높은 가용성에 결정적이다: 일부 워크로드는 ACL 데이터에 하부 데이터베이스 서버를 압도할 수 있는 핫스팟을 만든다. 흔한 패턴은 여러 다른 객체의 ACL이 간접적으로 참조하는 한 객체에 대해 ACL 검사가 폭주하는 것이다. 구체적인 사례로는 앞서 언급한 검색 사용 사례에서 검색 대상 문서들이 대규모 소셜 그룹이나 업무 그룹에 대한 ACL을 간접적으로 공유하는 경우, 그리고 많은 객체가 계층 구조 상위에 있는 같은 객체에 대한 ACL을 간접적으로 공유하는 Cloud 사용 사례가 있다. Zanzibar는 분산 캐시와 락 테이블 같은 일반적인 메커니즘으로 대부분의 핫스팟을 처리하지만, 특정 사용 사례를 최적화할 필요가 있음을 알게 되었다. 예를 들어 핫 객체에 대한 모든 관계 튜플의 캐시 프리페칭을 추가했다. 또한 같은 ACL 데이터에 대한 동시 요청이 있을 때는 부차적인 ACL 검사의 취소를 지연시켰다. §3.2.5를 참조하라.
- 성능 격리는 오작동하는 클라이언트로부터 보호하는 데 필수적이다: 핫스팟 완화 조치가 있더라도, 예상치 못한, 때로는 의도치 않은 클라이언트 동작이 여전히 시스템이나 그 하부 인프라에 과부하를 일으킬 수 있다. 예를 들어 클라이언트가 출시한 새 기능이 예상 외로 인기를 끌거나, Zanzibar를 의도하지 않은 방식으로 사용하는 경우가 있다. 시간이 지나면서 우리는 클라이언트 간 또는 같은 클라이언트의 객체 간에 연쇄 장애가 발생하지 않도록 격리 안전장치를 추가했다. 이러한 안전장치에는 세분화된 비용 산정, 할당량, 스로틀링이 포함된다. §3.2.6을 참조하라.
Zanzibar is a planet-scale distributed ACL storage and evaluation system. Many of its authorization concepts have been explored previously within the domains of access control and social graphs, and its scaling challenges have been investigated within the field of distributed systems.
Zanzibar는 행성 규모의 분산 ACL 저장 및 평가 시스템이다. Zanzibar의 인가 개념 중 다수는 접근 제어와 소셜 그래프 분야에서 이미 탐구되었으며, 확장성 과제는 분산 시스템 분야에서 연구되어 왔다.
Access control is a core part of multi-user operating systems. Multics [23] supports ACLs on segments and directories. ACL entries consist of a principal identifier and a set of permissions bits. In the first edition of UNIX [9], file flags indicate whether owner and non-owner can read or write the file. By the 4th edition, the permissions bits had been expanded to read/write/execute bits for owner, group, and others. POSIX ACLs [4] add an arbitrary list of users and groups, each with up to 32 permissions bits. VMS [7, 8] supports ACL inheritance for files created within a directory tree. Zanzibar’s data model supports permissions, users, groups, and inheritance as found in the above systems.
접근 제어는 다중 사용자 운영 체제의 핵심 부분이다. Multics [23]는 세그먼트와 디렉터리에 대한 ACL을 지원한다. ACL 항목은 주체(principal) 식별자와 권한 비트 집합으로 구성된다. UNIX 초판 [9]에서는 파일 플래그가 소유자와 비소유자가 파일을 읽거나 쓸 수 있는지를 나타낸다. 제4판에 이르러 권한 비트는 소유자, 그룹, 기타 사용자에 대한 읽기/쓰기/실행 비트로 확장되었다. POSIX ACL [4]은 사용자와 그룹의 임의 목록을 추가하며, 각각 최대 32개의 권한 비트를 가진다. VMS [7, 8]는 디렉터리 트리 안에서 생성된 파일에 대한 ACL 상속을 지원한다. Zanzibar의 데이터 모델은 위 시스템들에서 볼 수 있는 권한, 사용자, 그룹, 상속을 지원한다.
Taos [24, 10] supports compound principals that incorporate how an identity has been transformed as it passes through a distributed system. For example, if user logged into workstation to access file server , would see requests authenticated as “ for ” rather than just . This would allow one to write an ACL on a user’s e-mail that would be accessible only to the user, and only if being accessed via the mail server. Abadi et al. discuss in [11] a model of group-based ACLs with support for compound identities. Their notion of “blessings” are similar to Zanzibar tuples. However, Zanzibar adopts a unified representation for ACLs and groups using usersets, while they are separate concepts in [11].
Taos [24, 10]는 신원이 분산 시스템을 거쳐 전달되면서 어떻게 변환되었는지를 반영하는 복합 주체(compound principal)를 지원한다. 예를 들어 사용자 가 파일 서버 에 접근하기 위해 워크스테이션 에 로그인했다면, 는 요청이 단순히 가 아니라 “ for ”로 인증된 것으로 보게 된다. 이를 통해 사용자의 이메일에 대해, 그 사용자만 접근할 수 있으며 메일 서버를 통해 접근하는 경우에만 접근 가능한 ACL을 작성할 수 있다. Abadi 등은 [11]에서 복합 신원을 지원하는 그룹 기반 ACL 모델을 논의한다. 이들의 “blessing” 개념은 Zanzibar 튜플과 유사하다. 그러나 Zanzibar는 유저셋을 사용하여 ACL과 그룹을 통합된 방식으로 표현하는 반면, [11]에서는 이 둘이 별개의 개념이다.
Role-based access control (RBAC), first proposed in [17], introduced the notion of roles, which are similar to Zanzibar relations. Roles can inherit from each other and imply permissions. A number of Zanzibar clients have implemented RBAC policies on top of Zanzibar’s namespace configuration language.
[17]에서 처음 제안된 역할 기반 접근 제어(RBAC)는 Zanzibar의 관계와 유사한 역할이라는 개념을 도입했다. 역할은 서로 상속할 수 있으며 권한을 함축한다. 여러 Zanzibar 클라이언트가 Zanzibar의 네임스페이스 설정 언어 위에 RBAC 정책을 구현했다.
A discussion of ACL stores in 2019 would be remiss without mentioning the Identity and Access Management (IAM) systems offered commercially by Amazon [1], Google [5], Microsoft [2], and others. These systems allow customers of those companies’ cloud products to configure flexible access controls based on various features such as: assigning users to roles or groups; domain-specific policy languages; and APIs that allow the creation and modification of ACLs. What all of these systems have in common is unified ACL storage and an RPC-based API, a philosophy also core to Zanzibar’s design. Google’s Cloud IAM system [5] is built as a layer on top of Zanzibar’s ACL storage and evaluation system.
2019년에 ACL 저장소를 논하면서 Amazon [1], Google [5], Microsoft [2] 등이 상용으로 제공하는 ID 및 접근 관리(IAM) 시스템을 언급하지 않는다면 태만일 것이다. 이러한 시스템을 통해 해당 기업의 클라우드 제품 고객은 다양한 기능을 바탕으로 유연한 접근 제어를 설정할 수 있다. 이러한 기능에는 사용자를 역할이나 그룹에 할당하는 것, 도메인 특화 정책 언어, 그리고 ACL의 생성과 수정을 가능하게 하는 API가 있다. 이 모든 시스템의 공통점은 통합된 ACL 저장소와 RPC 기반 API인데, 이는 Zanzibar 설계의 핵심 철학이기도 하다. Google의 Cloud IAM 시스템 [5]은 Zanzibar의 ACL 저장 및 평가 시스템 위의 계층으로 구축되어 있다.
TAO [13] is a distributed datastore for Facebook’s social graph. Several Zanzibar clients also use Zanzibar to store their social graphs. Both Zanzibar and TAO provide authorization checks to clients. Both are deployed as single-instance services, both operate at a large scale, and both are optimized for read-only operations. TAO offers eventual global consistency with asynchronous replication and best-effort read-after-write consistency with synchronous cache updates. In contrast, Zanzibar provides external consistency and snapshot reads with bounded staleness, so that it respects causal ordering between ACL and content updates and thus protects against the “new enemy” problem.
TAO [13]는 Facebook의 소셜 그래프를 위한 분산 데이터 저장소다. 여러 Zanzibar 클라이언트도 Zanzibar를 사용하여 소셜 그래프를 저장한다. Zanzibar와 TAO는 모두 클라이언트에 인가 검사를 제공한다. 둘 다 단일 인스턴스 서비스로 배포되고, 둘 다 대규모로 운영되며, 둘 다 읽기 전용 작업에 최적화되어 있다. TAO는 비동기 복제를 통한 최종적 글로벌 일관성과, 동기식 캐시 갱신을 통한 최선 노력(best-effort) 방식의 쓰기 후 읽기 일관성을 제공한다. 반면 Zanzibar는 외부 일관성과 오래된 정도가 제한된 스냅샷 읽기를 제공하므로, ACL 갱신과 콘텐츠 갱신 사이의 인과적 순서를 준수하며 따라서 “new enemy” 문제를 막는다.
Lamport clocks [22] provide partially ordered vector timestamps that can be used to determine the order of events. However, Lamport clocks require explicit participation of all “processes”, where in Zanzibar’s use cases some of the “processes” can be external clients or even human users. In contrast, Zanzibar relies on its underlying database system, Spanner [15], to offer both external consistency and snapshot reads with bounded staleness. In particular, Zanzibar builds on Spanner’s TrueTime abstraction [15] to provide linearizable commit timestamps encoded as zookies.
Lamport 시계 [22]는 사건의 순서를 결정하는 데 사용할 수 있는 부분 순서 벡터 타임스탬프를 제공한다. 그러나 Lamport 시계는 모든 “프로세스”의 명시적인 참여를 요구하는데, Zanzibar의 사용 사례에서는 “프로세스” 중 일부가 외부 클라이언트이거나 심지어 인간 사용자일 수 있다. 반면 Zanzibar는 외부 일관성과 오래된 정도가 제한된 스냅샷 읽기를 모두 제공하기 위해 하부 데이터베이스 시스템인 Spanner [15]에 의존한다. 특히 Zanzibar는 Spanner의 TrueTime 추상화 [15]를 기반으로 zookie로 인코딩되는 선형화 가능한 커밋 타임스탬프를 제공한다.
At the same time, Zanzibar adds a number of features on top of those provided by Spanner. For one, the zookie protocol does not let clients read or evaluate ACLs at an arbitrary snapshot. This restriction allows Zanzibar to choose a snapshot that facilitates fast ACL evaluation. In addition, Zanzibar provides resilience to database hotspots (e.g. authorization checks on a suddenly popular video) and safe pointer chasing despite potentially deep recursion (e.g. membership checks on hierarchical groups).
동시에 Zanzibar는 Spanner가 제공하는 기능 위에 여러 기능을 추가한다. 우선 zookie 프로토콜은 클라이언트가 임의의 스냅샷에서 ACL을 읽거나 평가하도록 허용하지 않는다. 이 제약 덕분에 Zanzibar는 빠른 ACL 평가에 유리한 스냅샷을 선택할 수 있다. 또한 Zanzibar는 데이터베이스 핫스팟(예를 들어 갑자기 인기를 얻은 동영상에 대한 인가 검사)에 대한 복원력과, 잠재적으로 깊은 재귀(예를 들어 계층적 그룹에 대한 멤버십 검사)에도 불구하고 안전한 포인터 추적을 제공한다.
The Chubby distributed lock service [14] offers reliable storage, linearizes writes, and provides access control, but it lacks features needed to support Zanzibar’s use cases. In particular, it does not support high volumes of data, efficient range reads, or reads at a client-specified snapshot with bounded staleness. Its cache invalidation mechanism also limits its write throughput.
Chubby 분산 락 서비스 [14]는 신뢰할 수 있는 저장소를 제공하고, 쓰기를 선형화하며, 접근 제어를 제공하지만, Zanzibar의 사용 사례를 지원하는 데 필요한 기능이 부족하다. 특히 대용량 데이터, 효율적인 범위 읽기, 또는 클라이언트가 지정한 스냅샷에서 오래된 정도가 제한된 읽기를 지원하지 않는다. 또한 캐시 무효화 메커니즘이 쓰기 처리량을 제한한다.
Finally, ZooKeeper offers a high-performance coordination service [19] but also lacks features required by Zanzibar. Relative to Chubby, it can handle higher read and write rates with more relaxed cache consistency. However, it does not provide external consistency for updates across different nodes since its linearizability is on a per-node basis. It also does not provide snapshot reads with bounded staleness.
마지막으로 ZooKeeper는 고성능 조정 서비스 [19]를 제공하지만 역시 Zanzibar가 요구하는 기능이 부족하다. Chubby에 비해 ZooKeeper는 더 완화된 캐시 일관성으로 더 높은 읽기 및 쓰기 속도를 처리할 수 있다. 그러나 선형화 가능성이 노드 단위로 보장되므로 서로 다른 노드에 걸친 갱신에 대해서는 외부 일관성을 제공하지 않는다. 또한 오래된 정도가 제한된 스냅샷 읽기도 제공하지 않는다.
The Zanzibar authorization system unifies access control data and logic for Google. Its simple yet flexible data model and configuration language support a variety of access control policies from both consumer and enterprise applications.
Zanzibar 인가 시스템은 Google의 접근 제어 데이터와 로직을 통합한다. 단순하면서도 유연한 데이터 모델과 설정 언어는 소비자용 애플리케이션과 기업용 애플리케이션 모두의 다양한 접근 제어 정책을 지원한다.
Zanzibar’s external consistency model is one of its most salient features. It respects the ordering of user actions, yet at the same time allows authorization checks to be evaluated at distributed locations without global synchronization.
Zanzibar의 외부 일관성 모델은 가장 두드러진 특징 중 하나다. 이 모델은 사용자 행동의 순서를 준수하면서도, 동시에 글로벌 동기화 없이 분산된 위치에서 인가 검사를 평가할 수 있게 한다.
Zanzibar employs other key techniques to provide scalability, low latency, and high availability. For example, it evaluates deeply or widely nested group membership with Leopard, a specialized index for efficient computation of set operations with snapshot consistency. As another example, it combines a distributed cache with a mechanism to deduplicate in-flight requests. It thus mitigates hot spots, a critical production issue when serving data on top of normalized, consistent storage. These measures together result in a system that scales to trillions of access control rules and millions of authorization requests per second.
Zanzibar는 확장성, 낮은 지연 시간, 높은 가용성을 제공하기 위해 다른 핵심 기법들도 사용한다. 예를 들어 스냅샷 일관성을 갖춘 효율적인 집합 연산을 위한 특수 인덱스인 Leopard로 깊게 또는 넓게 중첩된 그룹 멤버십을 평가한다. 또 다른 예로, 분산 캐시와 처리 중인 요청을 중복 제거하는 메커니즘을 결합한다. 이를 통해 정규화되고 일관된 저장소 위에서 데이터를 서빙할 때 중요한 프로덕션 문제인 핫스팟을 완화한다. 이러한 조치들이 함께 작용하여 수조 개의 접근 제어 규칙과 초당 수백만 건의 인가 요청으로 확장되는 시스템을 만든다.
Many people have made technical contributions to Zanzibar. We thank previous and recent members of the development team, including Dan Barella, Miles Chaston, Daria Jung, Alex Mendes da Costa, Xin Pan, Scott Smith, Matthew Steffen, Riva Tropp, and Yuliya Zabiyaka. We also thank previous and current members of the Site Reliability Engineering team, including Randall Bosetti, Hannes Eder, Robert Geisberger, Tom Li, Massimo Maggi, Igor Oks, Aaron Peterson, and Andrea Yu.
많은 사람이 Zanzibar에 기술적으로 기여했다. Dan Barella, Miles Chaston, Daria Jung, Alex Mendes da Costa, Xin Pan, Scott Smith, Matthew Steffen, Riva Tropp, Yuliya Zabiyaka를 비롯한 개발 팀의 이전 및 최근 구성원에게 감사한다. 또한 Randall Bosetti, Hannes Eder, Robert Geisberger, Tom Li, Massimo Maggi, Igor Oks, Aaron Peterson, Andrea Yu를 비롯한 사이트 신뢰성 엔지니어링(SRE) 팀의 이전 및 현재 구성원에게도 감사한다.
In addition, a number of people have helped to improve this paper. We received insightful comments from David Bacon, Carolin Gäthke, Brad Krueger, Ari Shamash, Kai Shen, and Lawrence You. We are also grateful to Nadav Eiron and Royal Hansen for their support. Finally, we thank the anonymous reviewers and our shepherd, Eric Eide, for their constructive feedback.
또한 많은 사람이 이 논문을 개선하는 데 도움을 주었다. David Bacon, Carolin Gäthke, Brad Krueger, Ari Shamash, Kai Shen, Lawrence You로부터 통찰력 있는 의견을 받았다. Nadav Eiron과 Royal Hansen의 지원에도 감사드린다. 마지막으로 익명의 심사위원들과 셰퍼드인 Eric Eide의 건설적인 피드백에 감사한다.